
Type 5 EVPN/VXLAN GPU Backend Fabric, SLAAC IPv6 Overlay over IPv6 Link-Local Underlay - Configuration
This section outlines the configuration and verification steps to implement an EVPN/VXLAN fabric with:
- IPv6 GPU server NICs to Leaf Nodes connections using SLAAC
- IPv6 Leaf Nodes to Spine Nodes connections using link local addresses
- IPv6 GPU Backend Fabric underlay using BGP neighbor discovery
- IPv6 GPU Backend Fabric overlay
- Per Tenant IP-VRF Routing Instance
Details on how to implement IPv6 underlay/IPv4 overlay fabric (RFC5549), IPv4 underlay/IPv4 overlay fabric, and IPv6 underlay without SLAAC/IPv6 overlay fabric, have been included in Appendix A , Appendix B , and Appendix C respectively.
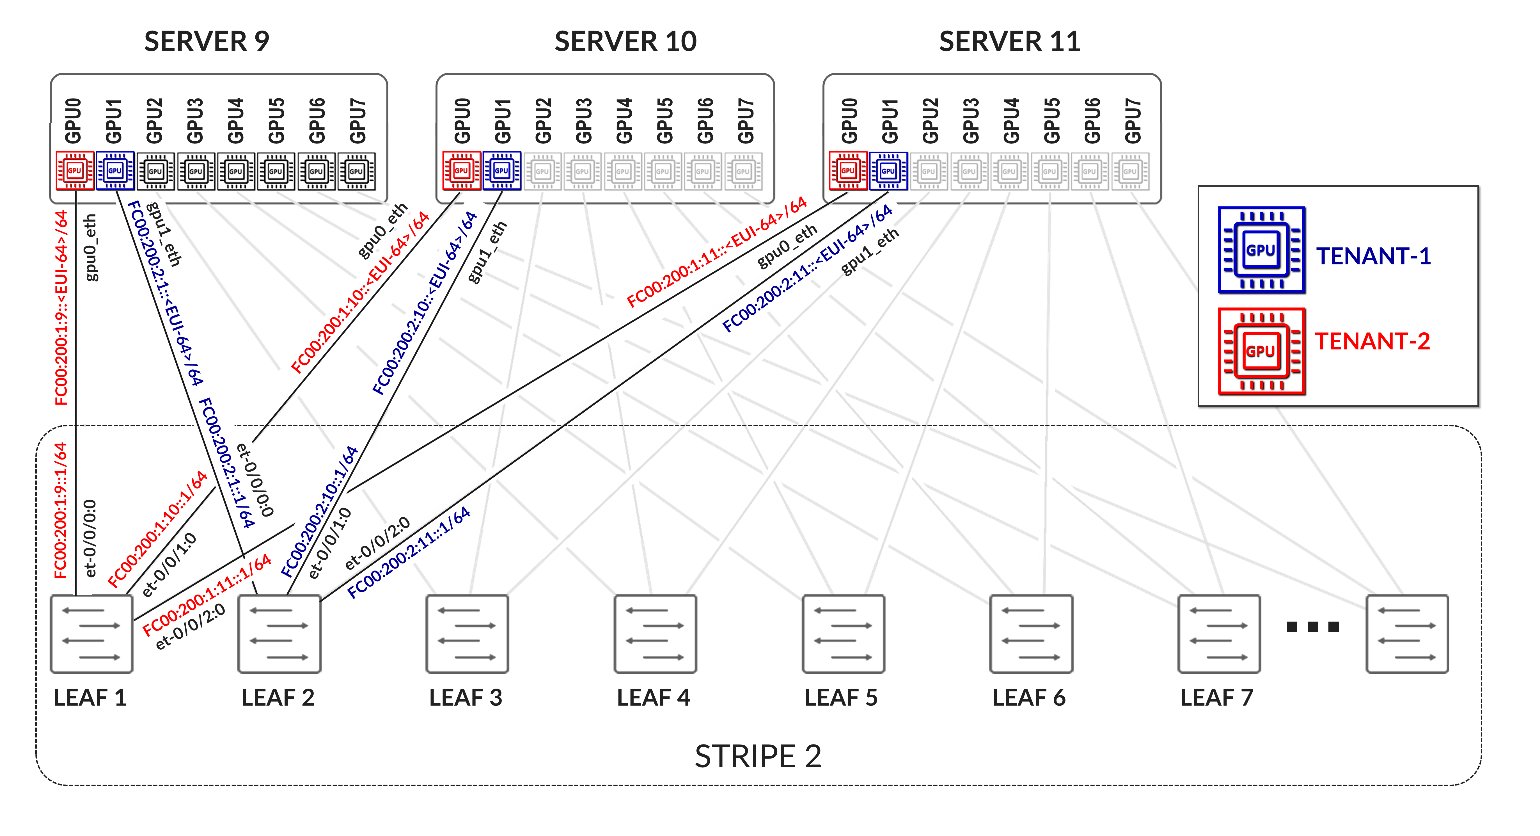
Consider the following scenario of a GPU-isolation implementation where:
| TENANT | SERVER | ASSIGNED GPUS |
|---|---|---|
| Tenant-1 |
SERVER 1, SERVER 2, SERVER 3 SERVER 9, SERVER 10, SERVER 11 |
GPU0 |
| Tenant-2 |
SERVER 1, SERVER 2, SERVER 3 SERVER 9, SERVER 10, SERVER 11 |
GPU1 |
Figure 45: Server-Isolation Example with Servers Across Multiple Stripes – Stripe 1
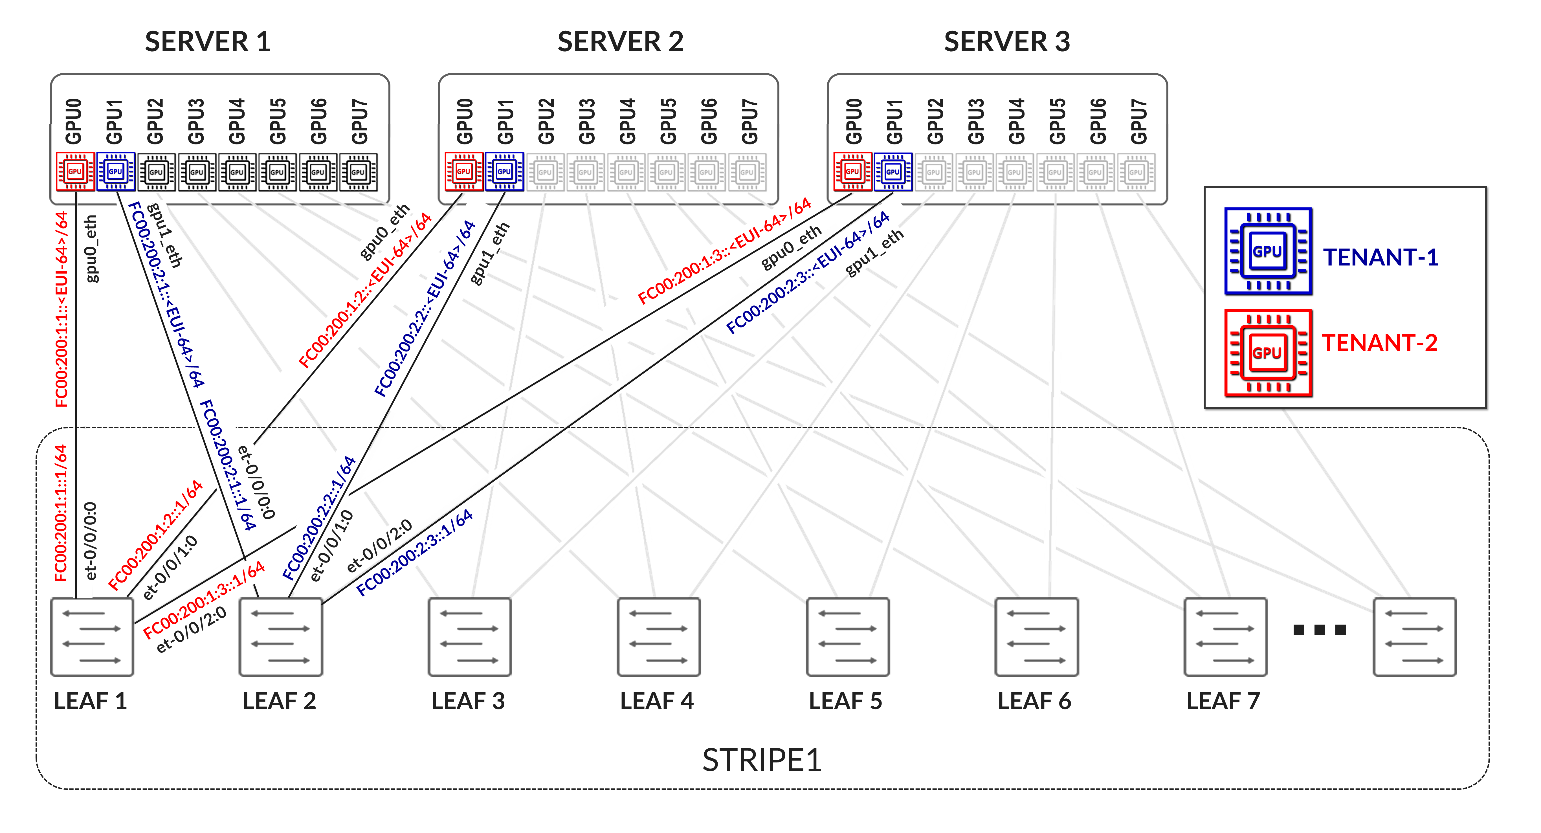
Figure 46: Server-Isolation Example with Servers Across Multiple Stripes – Stripe 2
IPv6 GPU Server NICs to Leaf Nodes Connections Using SLAAC
This section describes the operation of SLAAC in the context of this solution, and then will the configuration and verification steps on both the servers and the Leaf nodes.
The GPU servers are connected to the leaf nodes following a rail-aligned architecture as described in the Backend GPU Rail Optimized Stripe Architecture section, where GPU 0 is connected to the first Leaf node, GPU 1 is connected to the second leaf node and so on. This is shown in Figure 47.
Figure 47. GPU Servers Rail-Aligned Connectivity
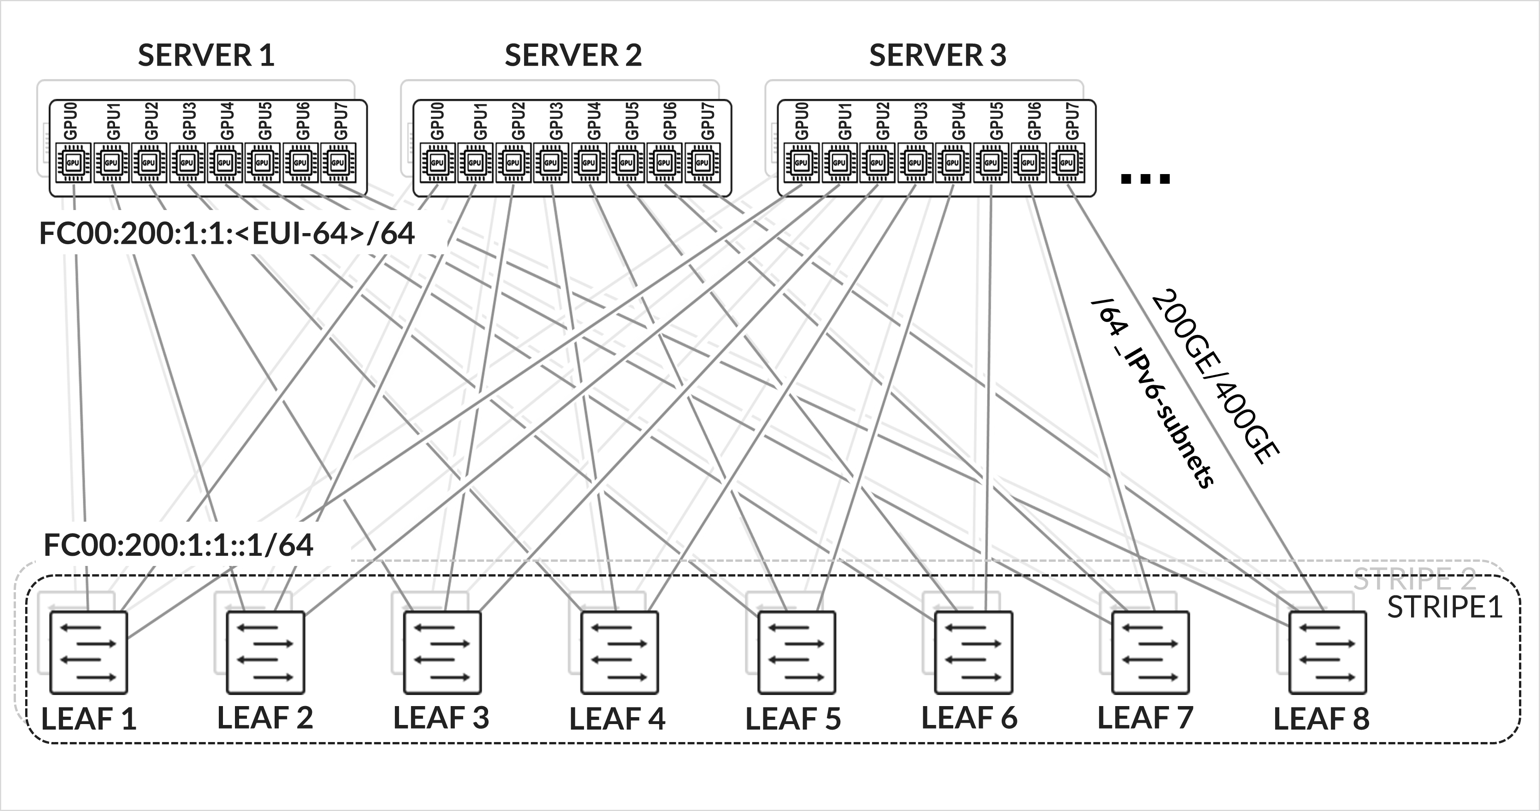
Each server to leaf node link is configured as an untagged L3 link and a statically configured /64 IPv6 address, while the server interface is autoconfigured using SLAAC to support scalable and automated IPv6 address assignment.
Each Tenant is assigned a /56 address, which will be used to derive /64 for each server to leaf node connection corresponding to the tenant. Tables 13 and 14 show the address assignment.
Table 13. Tenants /56 Prefixes Example
| TENANT | /56 IPv6 Prefix |
|---|---|
| Tenant-1 | FC00:200:1::/56 |
| Tenant-2 | FC00:200:2::/56 |
| Tenant-3 | FC00:200:3::/56 |
| Tenant-4 | FC00:200:4::/56 |
| Tenant-5 | FC00:200:5::/56 |
| Tenant-6 | FC00:200:6::/56 |
| Tenant-7 | FC00:200:7::/56 |
| Tenant-8 | FC00:200:8::/56 |
|
. . . |
Table 14. Tenants /64 Prefixes Example
| TENANT-1 | TENANT-2 | ... | |||
|---|---|---|---|---|---|
| Server to leaf Link | /64 Prefix | Server to leaf Link | /64 Prefix | ||
| SERVER 1 gpu0_eth ó Stripe 1 Leaf 1 | FC00:200:1:1::/64 | SERVER 1 gpu0_eth ó Stripe 1 Leaf 1 | FC00:200:2:1::/64 | ||
| SERVER 2 gpu0_eth ó Stripe 1 Leaf 1 | FC00:200:1:2::/64 | SERVER 2 gpu0_eth ó Stripe 1 Leaf 1 | FC00:200:2:2::/64 | ||
| SERVER 3 gpu0_eth ó Stripe 1 Leaf 1 | FC00:200:1:3::/64 | SERVER 3 gpu0_eth ó Stripe 1 Leaf 1 | FC00:200:2:3::/64 | ||
|
. . . |
. . . |
||||
| SERVER 9 gpu0_eth ó Stripe 2 Leaf 1 | FC00:200:1:9::/64 | SERVER 9 gpu0_eth ó Stripe 2 Leaf 1 | FC00:200:2:9::/64 | ||
| SERVER 10 gpu0_eth ó Stripe 2 Leaf 1 | FC00:200:1:10::/64 | SERVER 10 gpu0_eth ó Stripe 2 Leaf 1 | FC00:200:2:10::/64 | ||
| SERVER 11 gpu0_eth ó Stripe 2 Leaf 1 | FC00:200:1:11::/64 | SERVER 11 gpu0_eth ó Stripe 2 Leaf 1 | FC00:200:2:11::/64 | ||
|
. . . |
. . . |
||||
Each leaf node advertises a /64 IPv6 prefix, which is accepted by the server interface and used to automatically derive the interface’s IPv6 address through its EUI-64 identifier (based on the interface’s MAC address), as shown in Figure 48. This approach eliminates the need for DHCPv6 or manual configuration on the servers.
Figure 48: SLAAC – Stateless Address Autoconfiguration Operation Example – Tenant 1.
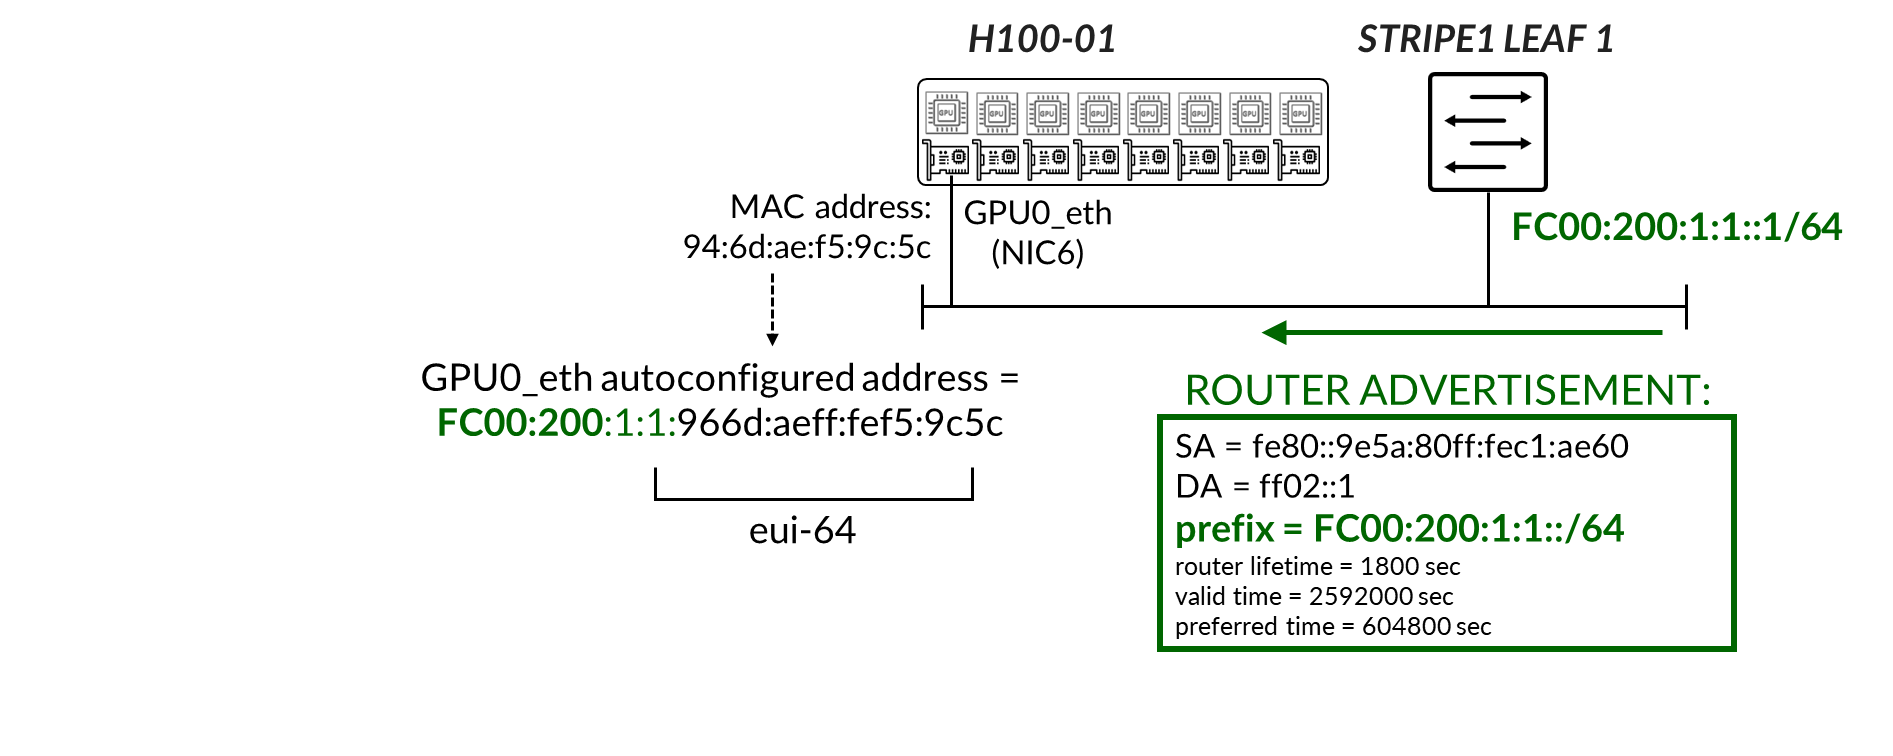
The leaf node must also advertise the tenant’s /56 prefix using the Route Information Option (RIO) in IPv6 router advertisement messages as shown in figure 48. This provides the routing information required for a given GPU interface to communicate with remote GPU interfaces assigned to the same tenant.
Figure 49: SLAAC – Stateless Address Autoconfiguration
with RIO-Prefix Operation Example – Tenant 1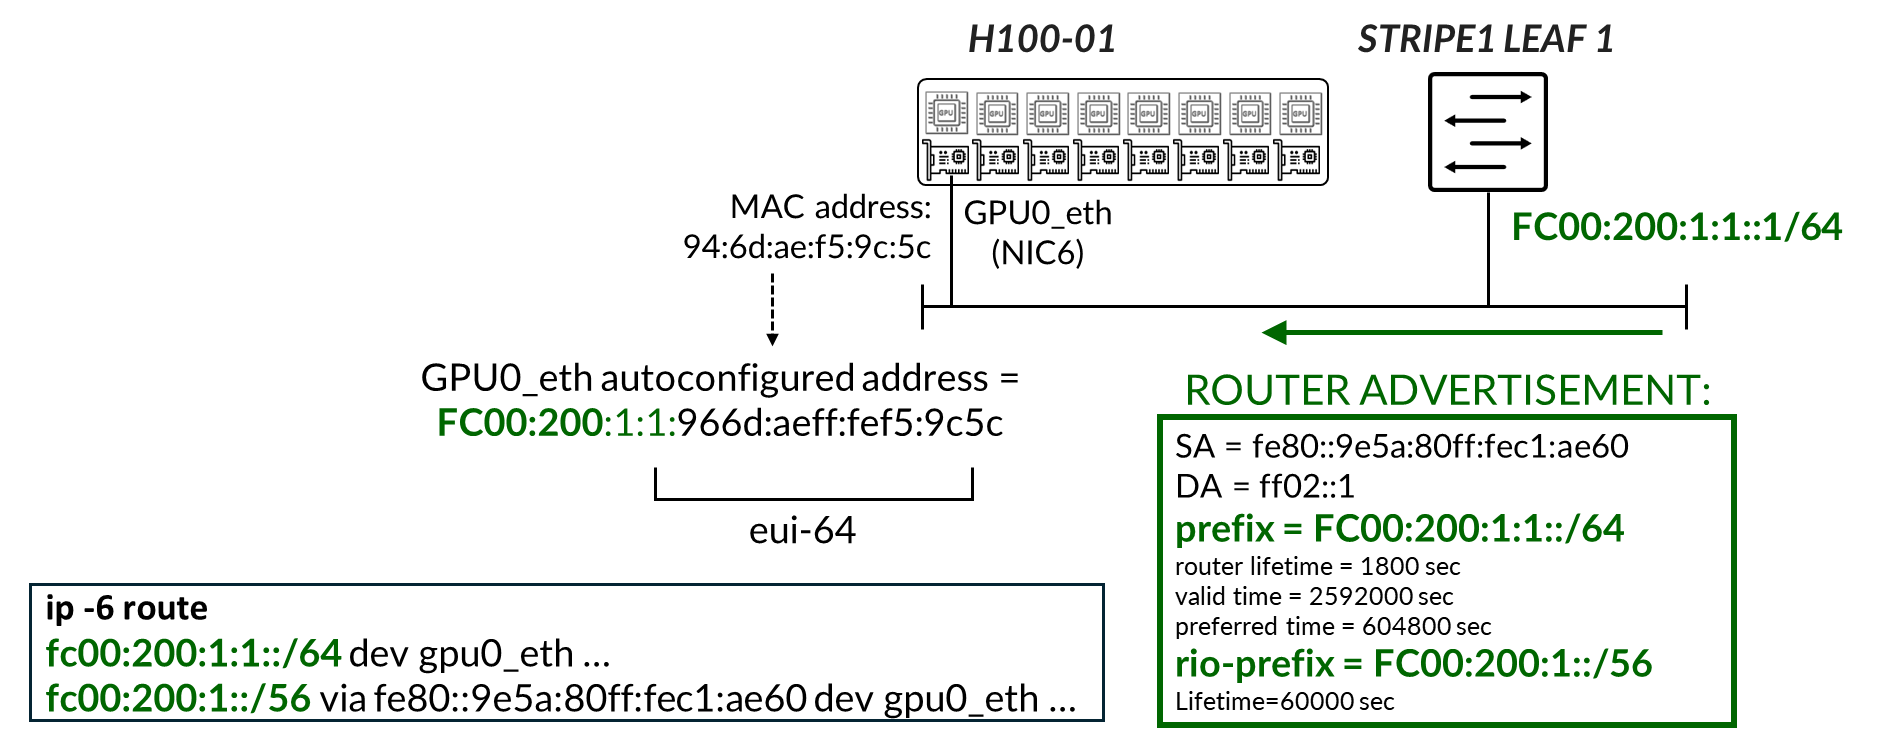
Without this option the server installs a default route pointing to the leaf node link local interface, for each RA received.
In the example shown in Figure 49, H100-01 and H100-02 provide GPU isolation for eight different tenants, with the following /56 prefix assignments:
Table 15. Tenants /56 Prefixes per Tenant Example
| TENANT | /56 Prefix |
|---|---|
| TENANT-1 | FC00:200:1::/56 |
| TENANT-2 | FC00:200:2::/56 |
| TENANT-3 | FC00:200:3::/56 |
| TENANT-4 | FC00:200:4::/56 |
| TENANT-5 | FC00:200:5::/56 |
| TENANT-6 | FC00:200:6::/56 |
| TENANT-7 | FC00:200:7::/56 |
| TENANT-8 | FC00:200:8::/56 |
|
. . . |
All interfaces associated with Tenant-1 will have IPv6 addresses derived from FC00:200:1::/56, all interfaces associated with Tenant-2 will have IPv6 addresses from FC00:200:2::/56, and so on, as shown in Figure 50.
Figure 50. Multitenancy GPU-Isolation Example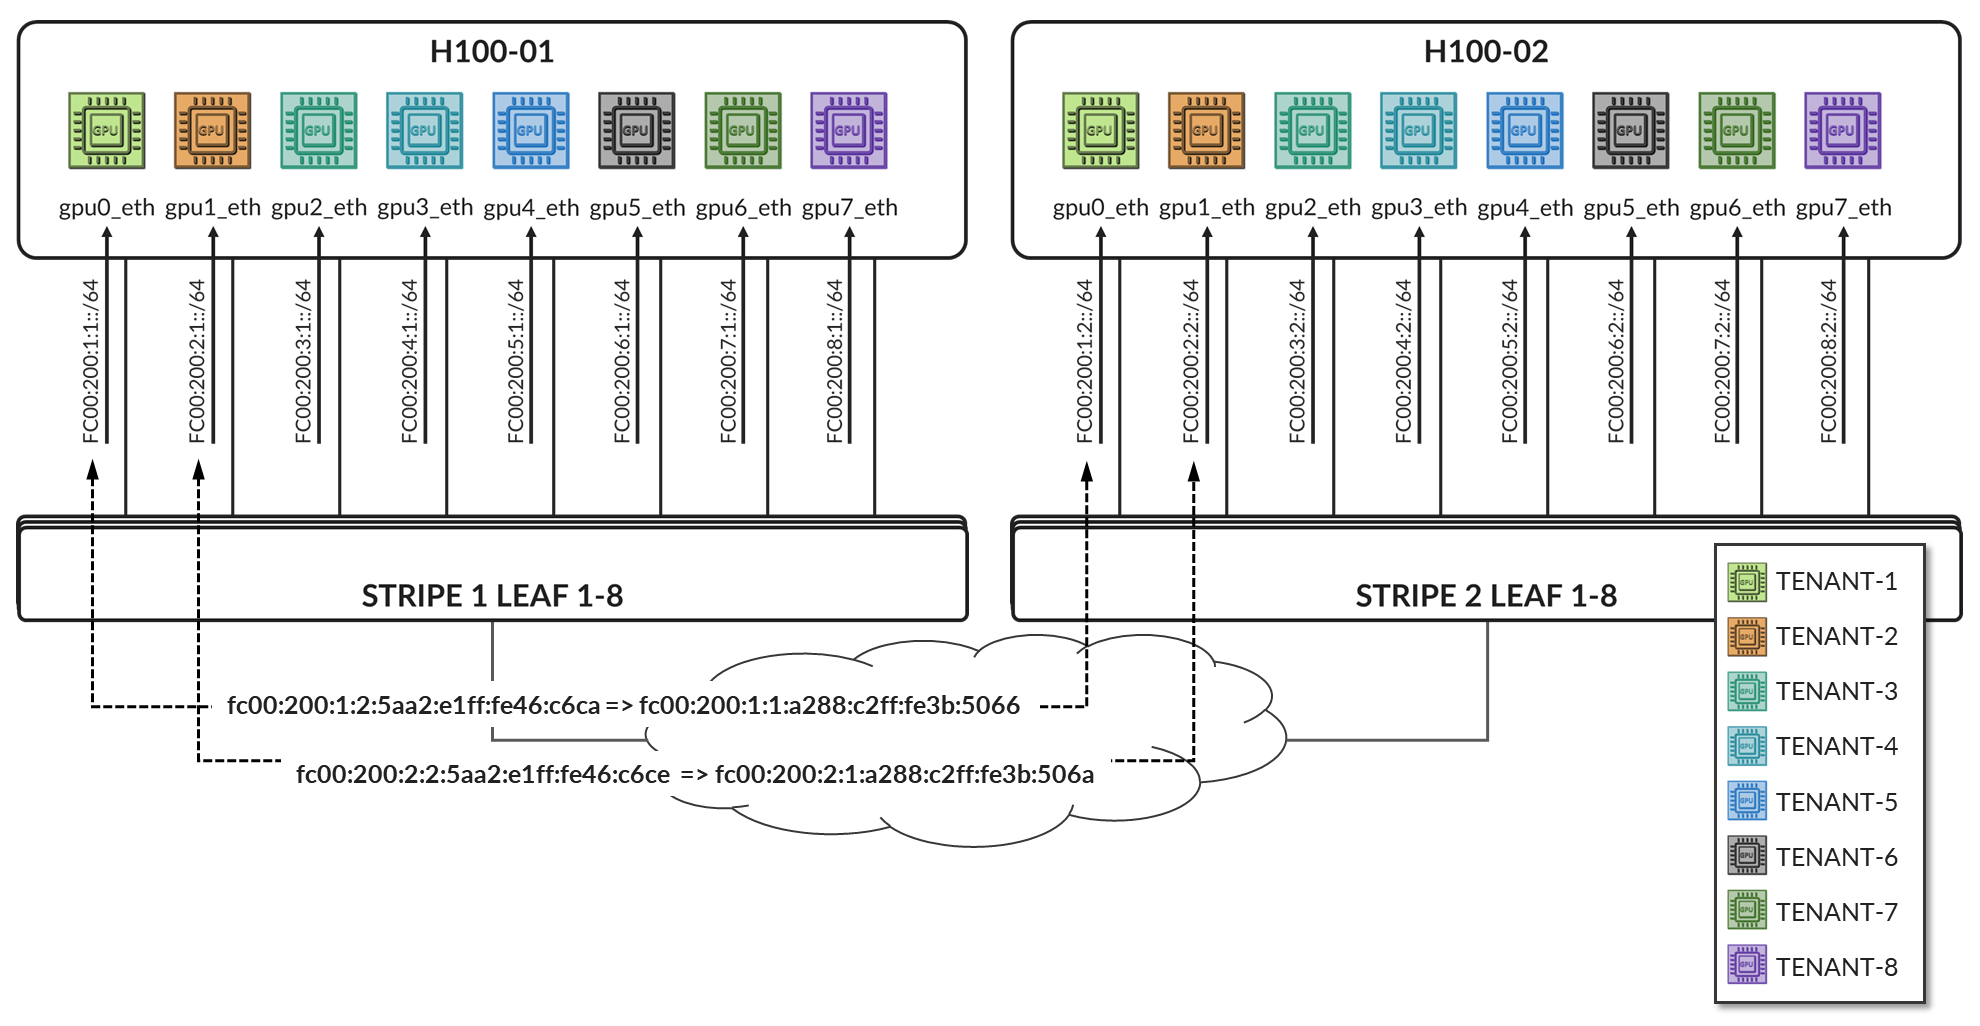
Initially, the leaf nodes are configured to advertise only the /64 prefixes. For example, Stripe 1 Leaf 1 advertises FC00:200:1:1::/64 to gpu0_eth server H100-01, while Stripe 2 Leaf 1 advertises FC00:200:1:2::/64 to gpu0_eth server H100-02. The two prefixes are derived from the FC00:200:1::/56 assigned to Tenant-1.
The servers automatically configure their IPv6 addresses from these advertised prefixes, as shown below:
jnpr@H100-01:~$ ifconfig | egrep "gpu|fc00"
gpu0_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:1:1:a288:c2ff:fe3b:5066 prefixlen 64  scopeid 0x0<global>
gpu1_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:2:1:a288:c2ff:fe3b:506a prefixlen 64  scopeid 0x0<global>
gpu2_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:3:1:a288:c2ff:fe3b:506e prefixlen 64  scopeid 0x0<global>
gpu3_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:4:1:a288:c2ff:fe3b:5072 prefixlen 64  scopeid 0x0<global>
gpu4_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:5:1:a288:c2ff:fe0a:7948 prefixlen 64  scopeid 0x0<global>
gpu5_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:6:1:a288:c2ff:fe0a:794c prefixlen 64  scopeid 0x0<global>
gpu6_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:6:1:a288:c2ff:fe0a:7940 prefixlen 64  scopeid 0x0<global>
gpu7_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:6:1:a288:c2ff:fe0a:7944 prefixlen 64  scopeid 0x0<global>
jnpr@H100-02:~$ ifconfig | egrep "gpu0|gpu1|fc00"
gpu0_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:1:2:5aa2:e1ff:fe46:c6ca prefixlen 64  scopeid 0x0<global>
gpu1_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:2:2:5aa2:e1ff:fe46:c6ce prefixlen 64  scopeid 0x0<global>
gpu2_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:1:2:5aa2:e1ff:fe46:c6d2  prefixlen 64  scopeid 0x0<global>
gpu3_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:2:2:5aa2:e1ff:fe46:c6d6  prefixlen 64  scopeid 0x0<global>
gpu4_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:1:2:5aa2:e1ff:fe46:c372  prefixlen 64  scopeid 0x0<global>
gpu5_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:2:2:5aa2:e1ff:fe46:c376 prefixlen 64  scopeid 0x0<global>
gpu6_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:1:2:5aa2:e1ff:fe46:c36a prefixlen 64  scopeid 0x0<global>
gpu7_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
        inet6 fc00:200:2:2:5aa2:e1ff:fe46:c36e prefixlen 64  scopeid 0x0<global>
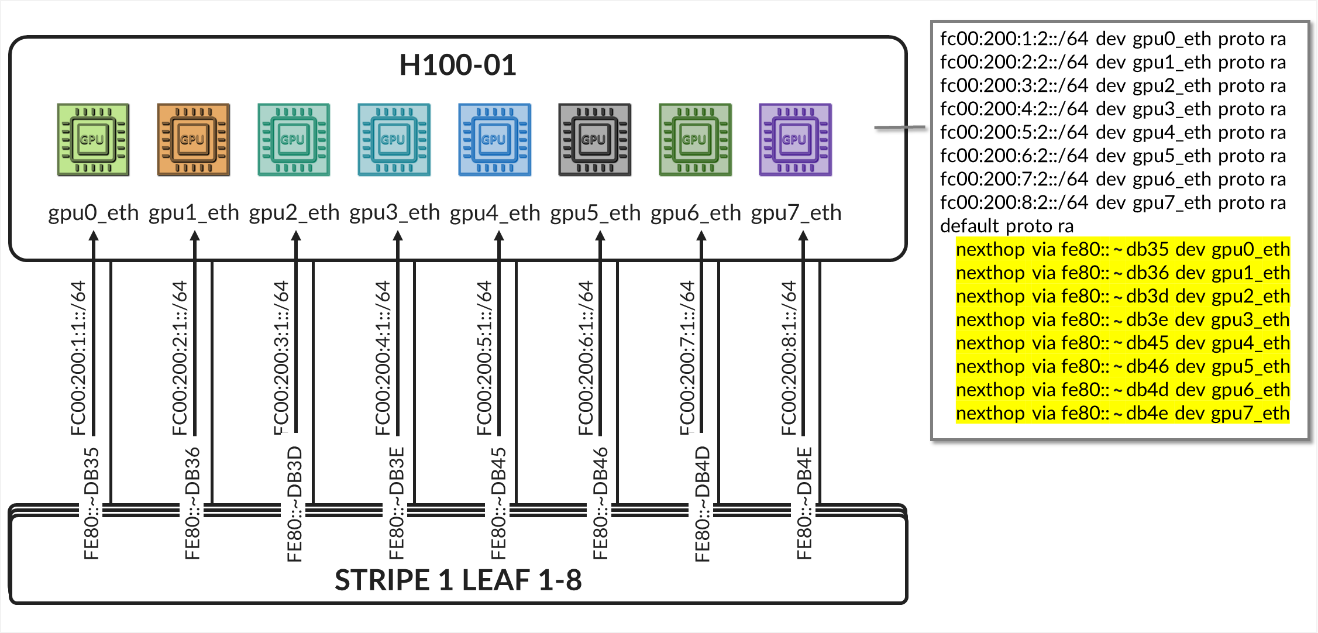
At this time, the routing tables on both servers include default routes pointing to the link local addresses learned from the router advertisements.
jnpr@H100-01:~$ ip -6 route
::1 dev lo proto kernel metric 256 pref medium
fc00:200:1:1::/64 dev gpu0_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:2:1::/64 dev gpu1_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:3:1::/64 dev gpu2_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:4:1::/64 dev gpu3_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:5:1::/64 dev gpu4_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:6:1::/64 dev gpu5_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:7:1::/64 dev gpu6_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:8:1::/64 dev gpu7_eth proto ra metric 1024 expires 2591984sec pref medium
fe80::/64 dev stor0_eth proto kernel metric 256 pref medium
fe80::/64 dev mgmt_eth proto kernel metric 256 pref medium
fe80::/64 dev eno3 proto kernel metric 256 pref medium
fe80::/64 dev gpu0_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu1_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu2_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu3_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu4_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu5_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu6_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu7_eth proto kernel metric 256 pref medium
default proto ra metric 1024 expires 1749sec pref medium
        nexthop via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae61 dev gpu1_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae68 dev gpu2_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae69 dev gpu3_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae70 dev gpu4_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae71 dev gpu5_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae78 dev gpu6_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae88 dev gpu7_eth weight 1

jnpr@H100-02:~$ ip -6 route
::1 dev lo proto kernel metric 256 pref medium
fc00:200:1:2::/64 dev gpu0_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:2:2::/64 dev gpu1_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:3:2::/64 dev gpu2_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:4:2::/64 dev gpu3_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:5:2::/64 dev gpu4_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:6:2::/64 dev gpu5_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:7:2::/64 dev gpu6_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:8:2::/64 dev gpu7_eth proto ra metric 1024 expires 2591885sec pref medium
fe80::/64 dev mgmt_eth proto kernel metric 256 pref medium
fe80::/64 dev eno3 proto kernel metric 256 pref medium
fe80::/64 dev stor0_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu0_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu1_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu2_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu3_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu4_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu5_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu6_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu7_eth proto kernel metric 256 pref medium
default proto ra metric 1024 expires 1685sec pref medium
       nexthop via fe80::5884:70ff:fe79:db35 dev gpu0_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db36 dev gpu1_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db3d dev gpu2_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db3e dev gpu3_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db45 dev gpu4_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db46 dev gpu5_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db4d dev gpu6_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db4e dev gpu7_eth weight 1
Traffic originating from gpu0_eth on H100-01 can successfully reach gpu0_eth on H100-02. However, traffic from gpu1_eth on H100-01 to gpu1_eth on H100-02 cannot. This is because, in both cases, the server selects the same default route, via gpu0_eth.
jnpr@H100-01:~$
ping fc00:200:1:2:5aa2:e1ff:fe46:c6ca -I fc00:200:1:1:a288:c2ff:fe3b:5066 -c 5
PING fc00:200:1:2:5aa2:e1ff:fe46:c6ca(fc00:200:1:2:5aa2:e1ff:fe46:c6ca) from fc00:200:1:1:a288:c2ff:fe3b:5066 : 56 data bytes
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=1 ttl=63 time=0.231 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=2 ttl=63 time=0.310 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=3 ttl=63 time=0.322 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=4 ttl=63 time=0.344 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=5 ttl=63 time=0.275 ms
--- fc00:200:1:2:5aa2:e1ff:fe46:c6ca ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4102ms
rtt min/avg/max/mdev = 0.231/0.296/0.344/0.039 ms
jnpr@H100-01:~$
ping fc00:200:2:2:5aa2:e1ff:fe46:c6ce -I fc00:200:2:1:a288:c2ff:fe3b:506a -c 5
PING fc00:200:2:2:5aa2:e1ff:fe46:c6ce(fc00:200:2:2:5aa2:e1ff:fe46:c6ce) from fc00:200:2:1:a288:c2ff:fe3b:506a : 56 data bytes
--- fc00:200:2:2:5aa2:e1ff:fe46:c6ce ping statistics ---
5 packets transmitted, 0 received, 100% packet loss, time 4090ms
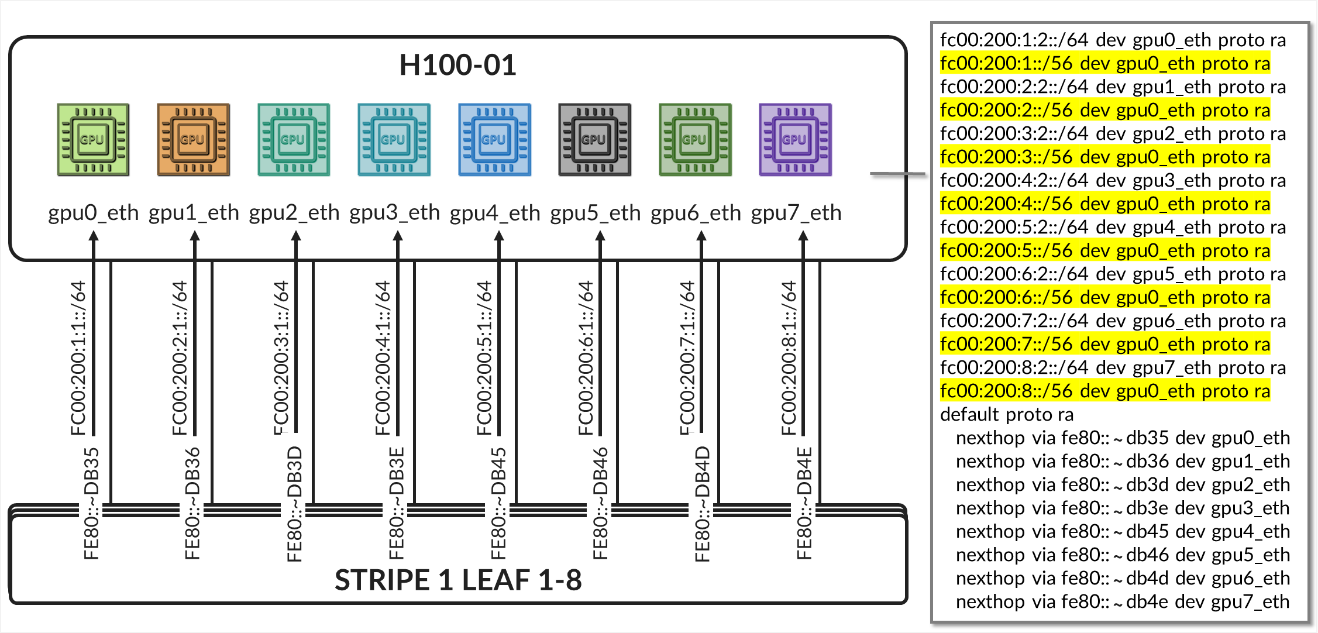
After enabling RIO-prefix advertisements, the leaf nodes not only advertise the /64 prefixes that the servers will use to autoconfigure their addresses, but also the /56 prefix assigned to the tenant. As a result, the servers install the /56 prefixes in their routing tables, pointing to the correct interfaces, and use these routes instead of the default route to reach any destination within the /56 prefix.
In the example, Stripe-1 Leaf-1 and Stripe-2 Leaf-1 advertise FC00:200:1:1::/64 and FC00:200:1:2::/64 to gpu0_eth on H100-01 and H100-02, respectively, and advertise the FC00:200:1::/56 prefix.
In the same way, Stripe-1 Leaf-1 and Stripe-2 Leaf-1 advertise FC00:200:2:1::/64 and FC00:200:2:2::/64 to gpu1_eth on H100-01 and H100-02, respectively, and advertise the FC00:200:2::/56 prefix.
As a result, the servers also install /56 routes in their routing tables, pointing to the correct interface. The servers then use these routes instead of the default route to reach any destination corresponding to Tenant-1 (FC00:200:1::/56) via gpu0_eth, and any destination corresponding to Tenant-2 (FC00:200:2::/56) via gpu1_eth.
jnpr@H100-01:~$ ip -6 route
::1 dev lo proto kernel metric 256 pref medium
fc00:200:1:1::/64 dev gpu0_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:1::/56 via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:2:1::/64 dev gpu1_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:2::/56 via fe80::9e5a:80ff:fec1:ae61 dev gpu1_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:3:1::/64 dev gpu2_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:3::/56 via fe80::9e5a:80ff:fec1:ae68 dev gpu2_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:4:1::/64 dev gpu3_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:4::/56 via fe80::9e5a:80ff:fec1:ae69 dev gpu3_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:5:1::/64 dev gpu4_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:5::/56 via fe80::9e5a:80ff:fec1:ae70 dev gpu4_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:6:1::/64 dev gpu5_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:6::/56 via fe80::9e5a:80ff:fec1:ae71 dev gpu5_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:7:1::/64 dev gpu6_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:7::/56 via fe80::9e5a:80ff:fec1:ae78 dev gpu6_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:8:1::/64 dev gpu7_eth proto ra metric 1024 expires 2591984sec pref medium
fc00:200:8::/56 via fe80::9e5a:80ff:fec1:ae88 dev gpu7_eth proto ra metric 100 expires 59841sec pref medium
fe80::/64 dev stor0_eth proto kernel metric 256 pref medium
fe80::/64 dev mgmt_eth proto kernel metric 256 pref medium
fe80::/64 dev eno3 proto kernel metric 256 pref medium
fe80::/64 dev gpu0_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu1_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu2_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu3_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu4_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu5_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu6_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu7_eth proto kernel metric 256 pref medium
default proto ra metric 1024 expires 1749sec pref medium
        nexthop via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae61 dev gpu1_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae68 dev gpu2_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae69 dev gpu3_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae70 dev gpu4_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae71 dev gpu5_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae78 dev gpu6_eth weight 1
        nexthop via fe80::9e5a:80ff:fec1:ae88 dev gpu7_eth weight 1

jnpr@H100-02:~$ ip -6 route
::1 dev lo proto kernel metric 256 pref medium
fc00:200:1:2::/64 dev gpu0_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:1::/56 via fe80::5884:70ff:fe79:db35 dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:2:2::/64 dev gpu1_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:2::/56 via fe80::5884:70ff:fe79:db36 dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:3:2::/64 dev gpu2_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:3::/56 via fe80::5884:70ff:fe79:db3d dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:4:2::/64 dev gpu3_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:4::/56 via fe80::5884:70ff:fe79:db3e dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:5:2::/64 dev gpu4_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:5::/56 via fe80::5884:70ff:fe79:db45 dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:6:2::/64 dev gpu5_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:6::/56 via fe80::5884:70ff:fe79:db46 dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:7:2::/64 dev gpu6_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:7::/56 via fe80::5884:70ff:fe79:db4d dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fc00:200:8:2::/64 dev gpu7_eth proto ra metric 1024 expires 2591885sec pref medium
fc00:200:8::/56 via fe80::5884:70ff:fe79:db4e dev gpu0_eth proto ra metric 100 expires 59841sec pref medium
fe80::/64 dev mgmt_eth proto kernel metric 256 pref medium
fe80::/64 dev eno3 proto kernel metric 256 pref medium
fe80::/64 dev stor0_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu0_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu1_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu2_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu3_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu4_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu5_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu6_eth proto kernel metric 256 pref medium
fe80::/64 dev gpu7_eth proto kernel metric 256 pref medium
default proto ra metric 1024 expires 1685sec pref medium
       nexthop via fe80::5884:70ff:fe79:db35 dev gpu0_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db36 dev gpu1_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db3d dev gpu2_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db3e dev gpu3_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db45 dev gpu4_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db46 dev gpu5_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db4d dev gpu6_eth weight 1
       nexthop via fe80::5884:70ff:fe79:db4e dev gpu7_eth weight 1
When sending traffic from fc00:200:1:1:a288:c2ff:fe3b:5066 to fc00:200:1:2:5aa2:e1ff:fe46:c6ca, H100-01 selects the fc00:200:1::/56 route via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth instead of the default route. Similarly, when sending traffic from fc00:200:2:1:a288:c2ff:fe3b:5066 to fc00:200:2:2:5aa2:e1ff:fe46:c6ca, H100-01 selects the fc00:200:2::/56 route via fe80::9e5a:80ff:fec1:ae81 dev gpu1_eth. In both cases, the correct next-hop and interface is selected, and the traffic is forwarded successfully.
jnpr@H100-01:~$ ping fc00:200:1:2:5aa2:e1ff:fe46:c6ca -I fc00:200:1:1:a288:c2ff:fe3b:5066 -c 5
PING fc00:200:1:2:5aa2:e1ff:fe46:c6ca(fc00:200:1:2:5aa2:e1ff:fe46:c6ca) from fc00:200:1:1:a288:c2ff:fe3b:5066 : 56 data bytes
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=1 ttl=63 time=0.598 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=2 ttl=63 time=0.555 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=3 ttl=63 time=0.552 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=4 ttl=63 time=0.594 ms
64 bytes from fc00:200:1:2:5aa2:e1ff:fe46:c6ca: icmp_seq=5 ttl=63 time=0.625 ms
--- fc00:200:1:2:5aa2:e1ff:fe46:c6ca ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4102ms
rtt min/avg/max/mdev = 0.552/0.584/0.625/0.027 ms
jnpr@H100-01:~$ ping fc00:200:2:2:5aa2:e1ff:fe46:c6ce -I fc00:200:2:1:a288:c2ff:fe3b:506a -c 5
PING fc00:200:2:2:5aa2:e1ff:fe46:c6ce(fc00:200:2:2:5aa2:e1ff:fe46:c6ce) from fc00:200:2:1:a288:c2ff:fe3b:506a : 56 data bytes
64 bytes from fc00:200:2:2:5aa2:e1ff:fe46:c6ce: icmp_seq=1 ttl=63 time=0.330 ms
64 bytes from fc00:200:2:2:5aa2:e1ff:fe46:c6ce: icmp_seq=2 ttl=63 time=0.285 ms
64 bytes from fc00:200:2:2:5aa2:e1ff:fe46:c6ce: icmp_seq=3 ttl=63 time=0.290 ms
64 bytes from fc00:200:2:2:5aa2:e1ff:fe46:c6ce: icmp_seq=4 ttl=63 time=0.283 ms
64 bytes from fc00:200:2:2:5aa2:e1ff:fe46:c6ce: icmp_seq=5 ttl=63 time=0.286 ms
--- fc00:200:2:2:5aa2:e1ff:fe46:c6ce ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4075ms
rtt min/avg/max/mdev = 0.283/0.294/0.330/0.017 ms
Server SLAAC Configuration:
The interfaces on the servers do not need to be configured with any IPv6 address. Disabling DHCPv6 is enough.
Example:
    gpu0_eth:
      match:
        macaddress: a0:88:c2:3b:50:66
      dhcp6: false
      mtu: 9000
      set-name: gpu0_eth
The servers must also be configured to accept and process RA messages, for IPv6 address autoconfiguration via Router Advertisements (RA) to work. In most cases, this will be enabled by default but the steps to enabled it are described here:
The configuration has two layers:
- Interface-level RA policy in Netplan or systemd
- Kernel-level sysctl parameters (accept_ra, autoconf)
Both must align to ensure proper RA behavior.
- If the system uses Netplan with systemd-networkd (common on Ubuntu Server):
In the Netplan YAML file (e.g., /etc/netplan/01-netcfg.yaml), add the following under each interface:
accept-ra: trueIPv6-privacy: falseThen apply the changes:
sudo netplan generatesudo netplan applyThis ensures that Netplan renders a .network file for systemd-networkd with IPv6AcceptRA=yes, which enables RA-based autoconfiguration.
However, this alone is not enough. If the kernel is still configured to ignore RAs. You must also verify that the kernel is set to accept RAs at runtime. You can check using:
sudo sysctl net.IPv6.conf.<interface>.accept_ra
If the value is 0, RAs will be ignored regardless of Netplan settings. This can be temporarily corrected with:
sudo sysctl -w net.IPv6.conf.<interface>.accept_ra=1
To make it persistent across reboots, add the following to a sysctl configuration file (e.g., /etc/sysctl.d/99-accept-ra.conf):
net.IPv6.conf.<interface>.accept_ra = 1
And apply it with:
sudo sysctl --system
Notice that parameters such as accept-ra can be enable or disable globally or on a per interface basis.
Table 17. Scope and Behavior of accept_ra Sysctl Parameters in IPv6 Configuration
| Sysctl | Scope | Effect |
|---|---|---|
| net.IPv6.conf.all.accept_ra | Global (all current interfaces) | Applies immediately to all existing interfaces, but... read-only if forwarding=1 |
| net.IPv6.conf.default.accept_ra | Global (for future interfaces) | Sets the default value used when a new interface comes up (e.g., plugged in or created later) |
| net.IPv6.conf.gpu0_eth.accept_ra | Per-interface | Controls RA processing for a specific active interface |
If the interface is managed directly by the kernel (not using Netplan/systemd):
Enable RA acceptance and autoconfiguration by setting:
sudo sysctl -w net.IPv6.conf.<interface>.accept_ra=1
sudo sysctl -w net.IPv6.conf.<interface>.autoconf=1
sudo tee /etc/sysctl.d/99-IPv6-ra.conf > /dev/null <<EOF
net.IPv6.conf.<interface>.accept_ra = 1
net.IPv6.conf.<interface>.autoconf = 1
EOF
sudo sysctl --system
Follow the steps in AMD Configuration | Juniper Networks to configure the interfaces on AMD GPU servers or NVIDIA Configuration | Juniper Networks for NVIDIA GPU servers.
Leaf Node SLAAC Configuration
To enable SLAAC, the leaf nodes must be explicitly configured with IPv6 addresses on the interfaces facing the GPU servers.
Example:
jnpr@stripe1-leaf1# show interface et-0/0/0:0
description " Multitenancy Tenant-1 GPU0 Server 1";
mtu 9216;
unit 0 {
    family inet6 {
        mtu 9140;
        address FC00:200:1:1::1/64;
    }
}
jnpr@stripe1-leaf1# show interface et-0/0/1:0
description "Multitenancy Tenant-1 GPU0 Server 2";
mtu 9216;
unit 0 {
    family inet6 {
        mtu 9140;
        address FC00:200:1:2::1/64;
    }
}
jnpr@stripe1-leaf1# show interface et-0/0/2:0
description "Multitenancy Tenant-1 GPU0 Server 3";
mtu 9216;
unit 0 {
    family inet6 {
        mtu 9140;
        address FC00:200:1:3::1/64;
    }
}
.
.
.
jnpr@stripe2-leaf1# show interface et-0/0/0:0
description "Multitenancy Tenant-1 GPU0 Server 9";
mtu 9216;
unit 0 {
    family inet6 {
        mtu 9140;
        address FC00:200:1:9::1/64;
    }
}
jnpr@stripe2-leaf1# show interface et-0/0/0:0
description "Multitenancy Tenant-1 GPU0 Server 10";
mtu 9216;
unit 0 {
    family inet6 {
        mtu 9140;
        address FC00:200:1:10::1/64;
    }
}
.
.
.
After assigning the IPv6 addresses, prefix advertisement must be enabled under the protocols router-advertisement hierarchy, as shown in the example below:
[edit protocols router-advertisement]
jnpr@stripe1-leaf1# show
interface et-0/0/0:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:1::1/64;
}
interface et-0/0/1:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:2::1/64;
}
interface et-0/0/2:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:3::1/64;
}
[edit protocols router-advertisement]
              jnpr@stripe1-leaf2# show
interface et-0/0/0:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:1::1/64;
}
interface et-0/0/1:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:2::1/64;
}
interface et-0/0/2:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:3::1/64;
}
The retransmit-timer 10000 configures the retransmission frequency of neighbor advertisements in milliseconds.
Configuring router advertisements for a given prefix requires that the interface itself has an IPv6 address within that same prefix. If the prefix specified under router-advertisement is not also configured on the interface, the commit will fail with an error.
Example:
[edit interfaces et-0/0/0:0]
jnpr@stripe1-leaf1# show
unit 0 {
    family inet6 {
        address FC00:255:1:1::1/64;
    }
}
[edit protocols router-advertisement]
jnpr@stripe1-leaf1# show
interface et-0/0/0:0.0 {
    prefix FC00:200:1:1::1/64;
}
[edit protocols router-advertisement interface et-0/0/12:0.0]
jnpr@stripe1-leaf1# commit
[edit protocols router-advertisement interface]
  'et-0/0/0.0'
    Family inet6 should be configured on this interface
error: commit failed: (statements constraint check failed)
Also, configure the rio-prefix under protocol router-advertisement, as shown in the example:
[edit protocols router-advertisement]
jnpr@stripe1-leaf1# show
interface et-0/0/0:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:1::/64;
    rio-prefix fc00:200:1::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/1:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:2::/64;
    rio-prefix fc00:200:1::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/2:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:3::/64;
    rio-prefix fc00:200:1::/56 {
        rio-lifetime 1800;
    }
}
.
.
.
[edit protocols router-advertisement]
jnpr@stripe1-leaf2# show
interface et-0/0/0:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:1::/64;
    rio-prefix fc00:200:2::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/1:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:2::/64;
    rio-prefix fc00:200:2::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/2:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:3::/64;
    rio-prefix fc00:200:2::/56 {
        rio-lifetime 1800;
    }
}
.
.
.
[edit protocols router-advertisement]
jnpr@stripe2-leaf1# show
interface et-0/0/0:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:9::/64;
    rio-prefix fc00:200:1::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/1:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:10::/64;
    rio-prefix fc00:200:1::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/2:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:1:11::/64;
    rio-prefix fc00:200:1::/56 {
        rio-lifetime 1800;
    }
}
.
.
.
[edit protocols router-advertisement]
jnpr@stripe2-leaf2# show
interface et-0/0/0:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:9::/64;
    rio-prefix fc00:200:2::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/1:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:10::/64;
    rio-prefix fc00:200:2::/56 {
        rio-lifetime 1800;
    }
}
interface et-0/0/2:0.0 {
    retransmit-timer 10000;
    prefix FC00:200:2:11::/64;
    rio-prefix fc00:200:2::/56 {
        rio-lifetime 1800;
    }
}
.
.
.
Notice that the lifetime is mandatory for the rio-prefix. In the example, this value is set 1800 seconds (30 minutes). The rio-prefix must be the /56 prefix assigned to the tenant, as described in the previous section.
SLAAC Verification:
To verify that RA-based configuration is working and that the GPU interface has
autoconfigured its IPv6 address, use: ip -6 addr show dev <interface> or
ifconfig <interface>
The command should display the interface’s link local address (FE80::<EUI-64>) and the global inet6 address generated by SLAAC (prefix::EUI-64). This global address will be marked as dynamic to indicate it was dynamically configured.
Example:
jnpr@H100-01:~$ ip -6 addr show dev gpu0_eth
17: gpu0_eth: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 9000 qdisc mq state UP group default qlen 1000
  inet6 fc00:200:1:1:a288:c2ff:fe3b:5066/64 scope global dynamic mngtmpaddr noprefixroute
       valid_lft 2591741sec preferred_lft 604541sec
  inet6 fe80::a288:c2ff:fe3b:5066/64 scope link
       valid_lft forever preferred_lft forever
jnpr@H100-01:~$ ifconfig gpu0_eth
gpu0_eth: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 9000
  inet6 fe80::a288:c2ff:fe3b:5066  prefixlen 64  scopeid 0x20<link>
  inet6 fc00:200:1:1:a288:c2ff:fe3b:5066  prefixlen 64  scopeid 0x0<global>
  ether a0:88:c2:3b:50:66  txqueuelen 1000  (Ethernet)
  RX packets 67096  bytes 5792577 (5.7 MB)
  RX errors 0  dropped 0  overruns 0  frame 0
  TX packets 20886  bytes 3122514 (3.1 MB)
  TX errors 0  dropped 0 overruns 0  carrier 0  collisions 0
You can also observe incoming RA messages using tcpdump: sudo tcpdump -i
<interface> -vv icmp6 and 'ip6[40] == 134'
Example:
jnpr@H100-01:~$ sudo tcpdump -i gpu0_eth -vv icmp6 and 'ip6[40] == 134'
tcpdump: listening on gpu0_eth, link-type EN10MB (Ethernet), snapshot length 262144 bytes
19:26:15.604130 IP6 (flowlabel 0xcbfef, hlim 255, next-header ICMPv6 (58) payload length: 72) fe80::9e5a:80ff:fec1:ae60 > ip6-allnodes: [icmp6 sum ok] ICMP6, router advertisement, length 72
        hop limit 64, Flags [none], pref medium, router lifetime 1800s, reachable time 0ms, retrans timer 0ms
          source link-address option (1), length 8 (1): 9c:5a:80:c1:ae:60
            0x0000:  9c5a 80c1 ae60
          prefix info option (3), length 32 (4): fc00:200:1:1::/64, Flags [onlink, auto], valid time 2592000s, pref. time 604800s
            0x0000:  40c0 0027 8d00 0009 3a80 0000 0000 fc00
            0x0010:  0200 0001 0001 0000 0000 0000 0000
          route info option (24), length 16 (2):  fc00:200:1::/56, pref=medium, lifetime=60000s
            0x0000:  3800 0000 ea60 fc00 0200 0001 0000
19:26:31.605713 IP6 (flowlabel 0xcbfef, hlim 255, next-header ICMPv6 (58) payload length: 72) fe80::9e5a:80ff:fec1:ae60 > ip6-allnodes: [icmp6 sum ok] ICMP6, router advertisement, length 72
        hop limit 64, Flags [none], pref medium, router lifetime 1800s, reachable time 0ms, retrans timer 0ms
          source link-address option (1), length 8 (1): 9c:5a:80:c1:ae:60
            0x0000:  9c5a 80c1 ae60
          prefix info option (3), length 32 (4): fc00:200:1:1::/64, Flags [onlink, auto], valid time 2592000s, pref. time 604800s
            0x0000:  40c0 0027 8d00 0009 3a80 0000 0000 fc00
            0x0010:  0200 0001 0001 0000 0000 0000 0000
          route info option (24), length 16 (2):  fc00:200:1::/56, pref=medium, lifetime=60000s
0x0000: 3800 0000 ea60 fc00 0200 0001 0000If a new prefix needs to be advertised on an interface, reconfigure the router advertisements to age out the old address and to advertise the new one.
jnpr@H100-01:/etc/netplan$ ip -6 addr show dev gpu0_eth
17: gpu0_eth: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 9000 qdisc mq state UP group default qlen 1000
 inet6 fc00:200:1:1:a288:c2ff:fe3b:5066/64 scope global dynamic mngtmpaddr noprefixroute
   valid_lft 2591988sec preferred_lft 604788sec
 inet6 fe80::a288:c2ff:fe3b:5066/64 scope link
   valid_lft forever preferred_lft forever
jnpr@H100-01:/etc/netplan$ ip -6 route | grep gpu0_eth
fc00:200:1:1::/64 dev gpu0_eth proto ra metric 100 expires 2591949sec pref medium
fc00:200:1::/56 via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth proto ra metric 100 expires 1749sec pref medium
fe80::/64 dev gpu0_eth proto kernel metric 256 pref medium
default via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth proto ra metric 100 expires 1749sec pref medium
[edit protocols router-advertisement]
jnpr@stripe1-leaf1#
  interface et-0/0/0:0 {
    /* DEPRECATED IPv6 PREFIX */
    prefix fc00:200:1:1::/64 {
      valid-lifetime 0;
      preferred-lifetime 0;
    }
    rio-prefix fc00:200:1::/56 {
      rio-lifetime 0;
    }
    /* NEW IPv6 PREFIX */
    prefix fc00:200:100:100::/64;
    rio-prefix fc00:200:100::/56 {
      rio-lifetime 1800;
    }
  }
jnpr@H100-01:/etc/netplan$ ip -6 addr show dev gpu0_eth
17: gpu0_eth: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 9000 qdisc mq state UP group default qlen 1000
    inet6 fc00:200:100:100:a288:c2ff:fe3b:5066/64 scope global tentative dynamic mngtmpaddr noprefixroute
       valid_lft 2591999sec preferred_lft 604799sec
    inet6 fe80::a288:c2ff:fe3b:5066/64 scope link
       valid_lft forever preferred_lft forever
jnpr@H100-01:/etc/netplan$ ip -6 route | grep gpu0_eth
fc00:200:100::/56 via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth proto ra metric 100 expires 1797sec pref medium
fc00:200:100:100::/64 dev gpu0_eth proto ra metric 100 expires 2591997sec pref medium
fe80::/64 dev gpu0_eth proto kernel metric 256 pref medium
default via fe80::9e5a:80ff:fec1:ae60 dev gpu0_eth proto ra metric 100 expires 1797sec pref medium
If you need to manually flush any IPv6 address from the server interface you can use the following commands:
sudo ip addr flush dev <interface>sudo ip link set
<interface> down && sleep 1&& sudo ip link set
<interface> up
After bringing the interface back up, wait a few seconds and re-check the IPv6 address with:
ip -6 addr show dev <interface>
This ensures that stale addresses are removed, and fresh RAs are processed.
All IPv6 settings can be found under: /proc/sys/net/IPv6/conf
To verify that router advertisements are being sent, you can use the following
command:show ipv6 router-advertisement interface <interface>
Example:
jnpr@stripe1-leaf1> show IPv6 router-advertisement interface et-0/0/0:0
Interface: et-0/0/0:0.0
  Advertisements sent: 3, last sent 00:01:48 ago
  Solicits sent: 1, last sent 00:02:20 ago
  Solicits received: 0
  Advertisements received: 0
  Solicited router advertisement unicast: Disable
  IPv6 RA Preference: DEFAULT/MEDIUM
  Passive mode: Disable
  Upstream mode: Disable
  Downstream mode: Disable
  Proxy blackout timer: Not Running
  Route Information: fc00:200:1::/56
    IPv6 RA Preference: DEFAULT/MEDIUM
    Route lifetime: 60000 sec
You can also capture router advertisement packets on the interface using: monitor
traffic interface et-0/0/0:0.0 extensive matching "icmp6 and ip6[40] == 134"
Example:
jnpr@stripe1-leaf1> monitor traffic interface et-0/0/0:0.0 extensive matching "icmp6 and ip6[40] == 134"
18:05:50.344868 9c:5a:80:c1:ae:60 > 33:33:00:00:00:01, ethertype IPv6 (0x86dd), length 188: (flowlabel 0x19976, hlim 255, next-header ICMPv6 (58) payload length: 56) fe80::9e5a:80ff:fec1:ae60 > ff02::1: [icmp6 sum ok] ICMP6, router advertisement, length 56
        hop limit 64, Flags [none], pref medium, router lifetime 1800s, reachable time 0ms, retrans timer 0ms
          source link-address option (1), length 8 (1): 9c:5a:80:c1:ae:60
            0x0000:  9c5a 80c1 ae60
          prefix info option (3), length 32 (4): fc00:200:1:1::/64, Flags [onlink, auto], valid time 2592000s, pref. time 604800s
            0x0000:  40c0 0027 8d00 0009 3a80 0000 0000 fc00
            0x0010:  0200 0001 0001 0000 0000 0000 0000
          route info option (24), length 16 (2):  fc00:200:1::/56, pref=medium, lifetime=60000s
Notice that Router Advertisements are sent using the link local address of the leaf node interfaces as source, the IPv6 all-nodes multicast address (FF02::1), next-header ICMPv6 (58). The following are the most relevant attributes for these:
Table 18. Fields and Semantics in IPv6 Router Advertisement
| PARAMETER | VALUE | DESCRIPTION |
|---|---|---|
| Flags | auto |
Hosts can assume addresses in this prefix are on the local link. This prefix can be used for SLAAC (Stateless Address Auto Configuration). |
| Flags | On-link | tells hosts which destinations are directly reachable without going through a router. |
| source link-address option | 9c:5a:80:c1:ae:60 | Tells the receiver the link-layer (MAC) address of the router sending the RA. The receiver knows the router’s MAC address without having to send a separate Neighbor Solicitation. |
| prefix info option | fc00:200:1:1::/64 | Advertises IPv6 prefixes that hosts can use to autoconfigured its IPv6 address. |
| route info option | fc00:200:1::/56 |
Carries routes to destinations other than the default. Routers can advertise more specific routes (beyond just “I’m the default gateway”). |
| Valid Lifetime | 2592000 | Prefix is valid for 30 days (used for reachability). |
| Preferred Lifetime | 604800 | Preferred lifetime of 7 days (after which it becomes deprecated for new connections). |
| router lifetime | 1800s | The router is considered a default gateway for 1800 seconds |
After receiving the router-advertisement, the server’s NIC interfaces will have autoconfigured their IPv6 addresses by concatenating the prefix advertise by the Leaf node, with the host portion of the address calculated using the EUI-64 address format (based on the interface’s MAC address), as shown in Table 19.
Table 19. GPU to Leaf nodes IPv6 addresses
| LEAF NODE INTERFACE |
LEAF NODE IPv6 ADDRESS |
GPU NIC |
GPU NIC MAC address |
GPU NIC IPv6 ADDRESS |
|---|---|---|---|---|
|
Stripe 1 Leaf 1 et-0/0/0:0 |
FC00:200:1:1::1/64 | Server 1 - gpu0_eth | a0:88:c2:3b:50:66 | FC00:200:1:1:a288:c2ff:fe3b:5066 |
|
Stripe 1 Leaf 1 et-0/0/1:0 |
FC00:200:1:2::1/64 | Server 2 - gpu0_eth | 58:a2:e1:46:c6:ca | FC00:200:1:2:a288:c2ff:fe3b:506a |
|
Stripe 2 Leaf 1 et-0/0/2:0 |
FC00:200:1:3::1/64 | Server 3 - gpu0_eth | a0:88:c2:3b:50:6e | FC00:200:1:3:a2:88:c2ff:fe3b:50:6e |
|
. . . |
IPv6 Leaf Nodes to Spine Nodes Connections Using Link Local Addresses
When deploying the underlay using IPv6 Link-Local underlay, the interfaces between the leaf and spine nodes do not require explicitly configured IP addresses and are configured as untagged interfaces with only family inet6 to enable processing of IPv6 traffic as shown in Figure 50.
Figure 50: Leaf Nodes to Spine Nodes Connectivity
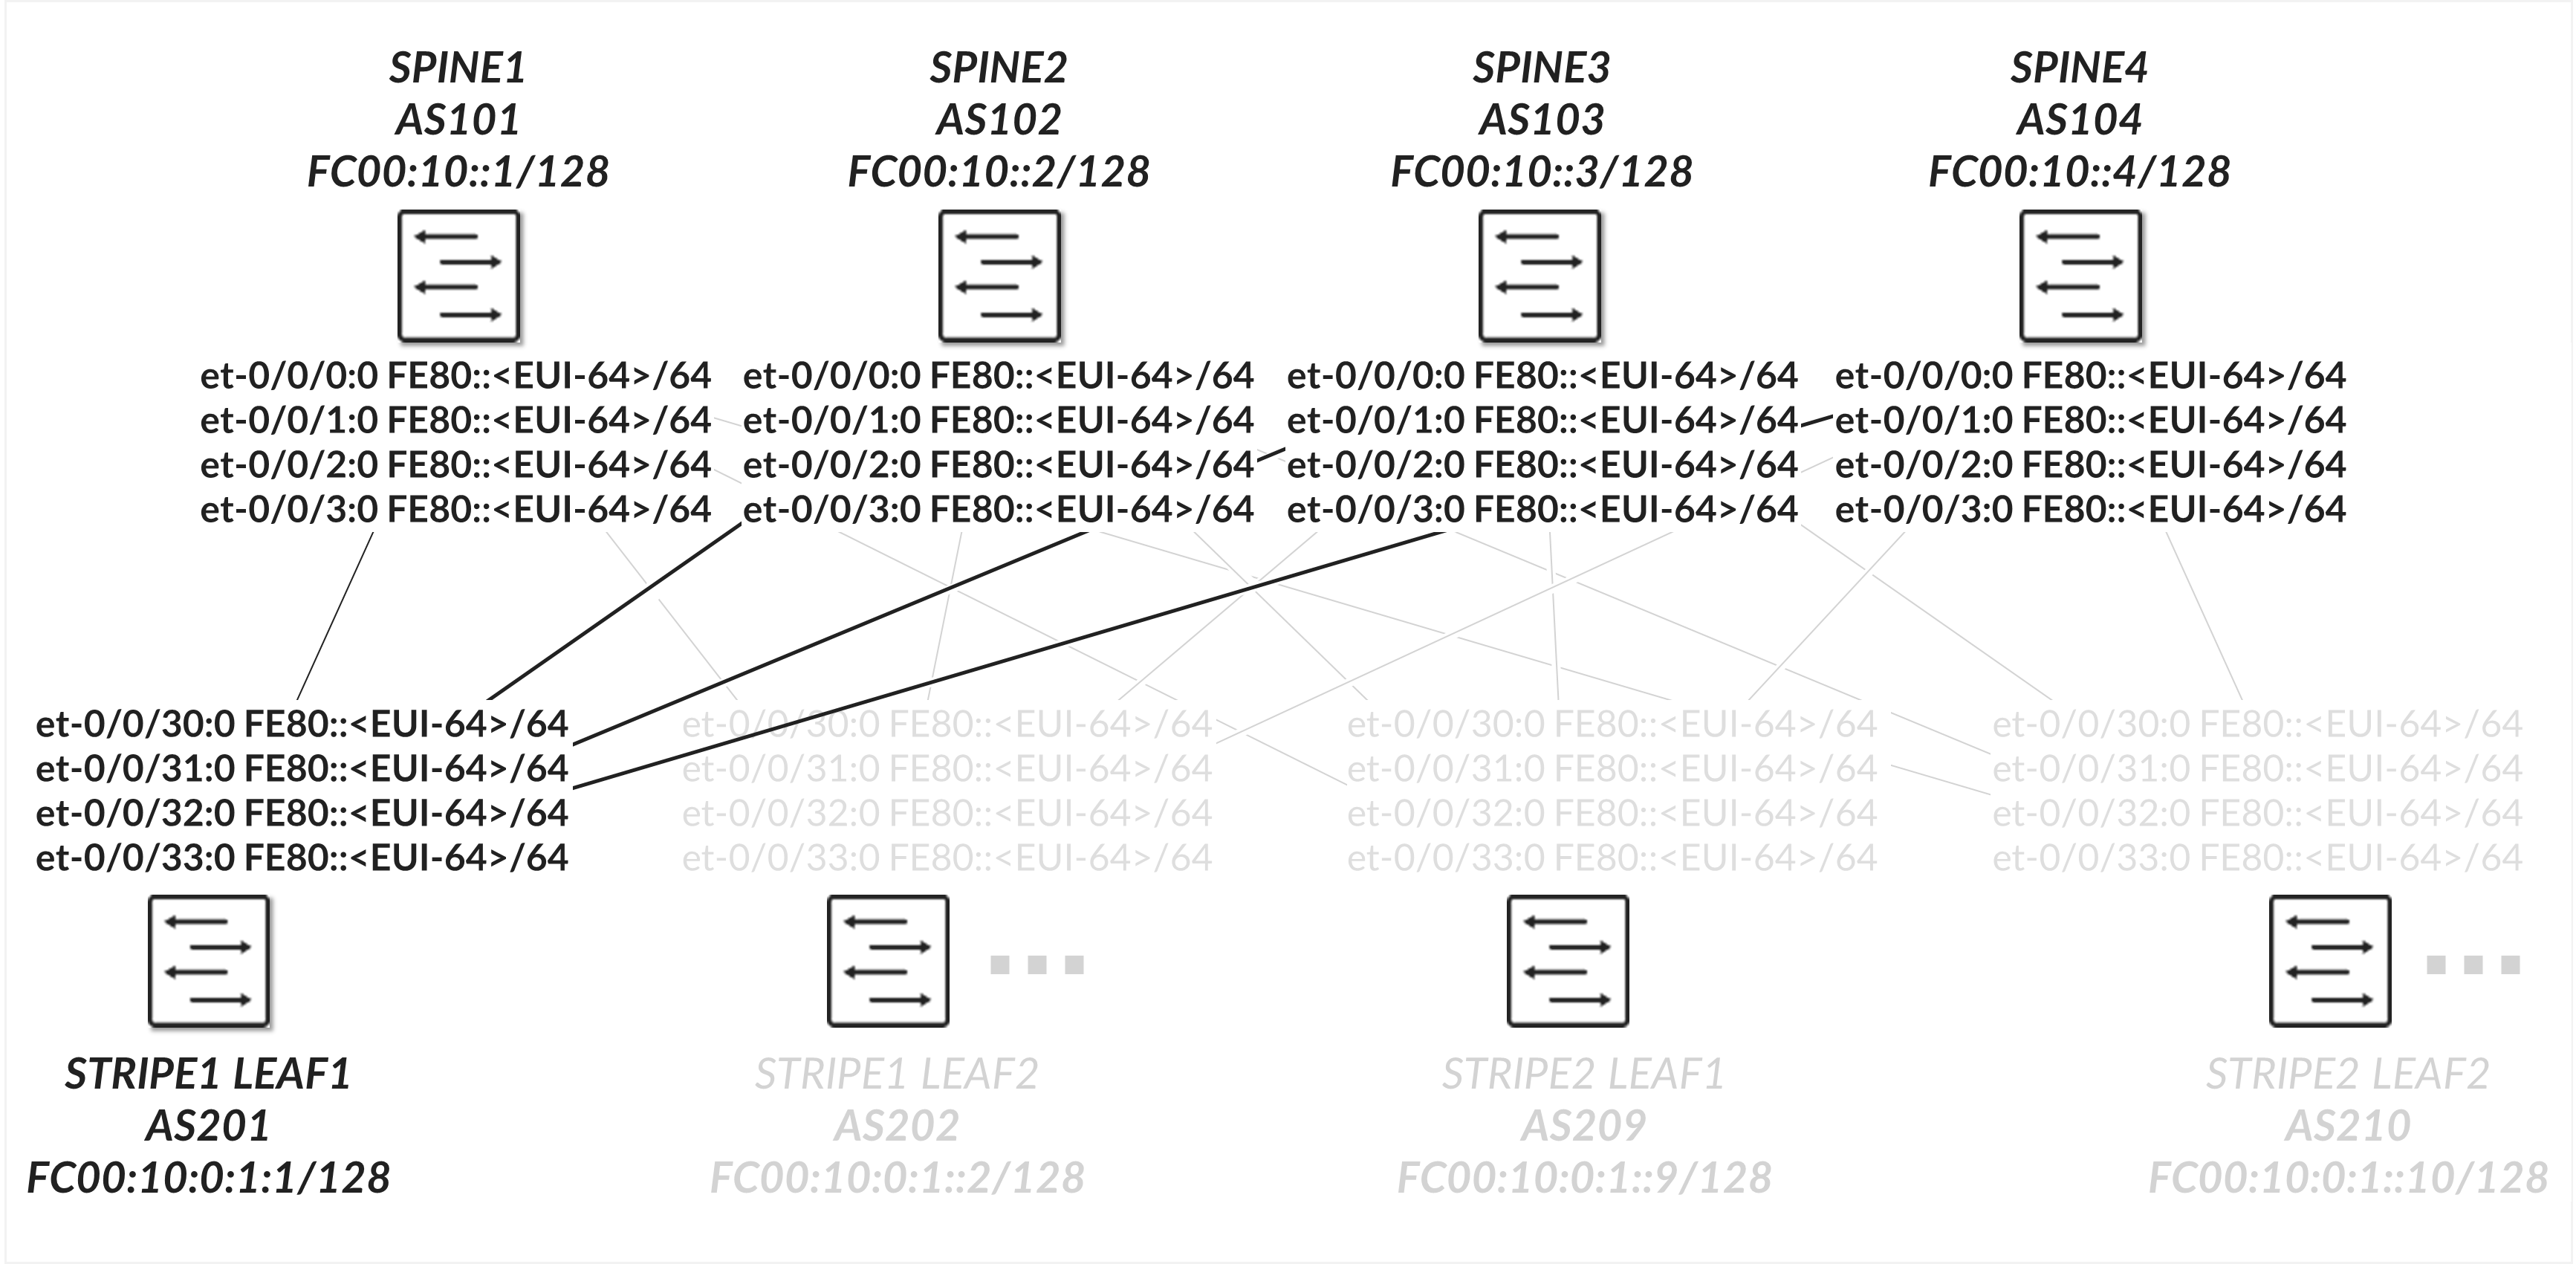
Table 20. Spine to Leaf Interface Configuration Example
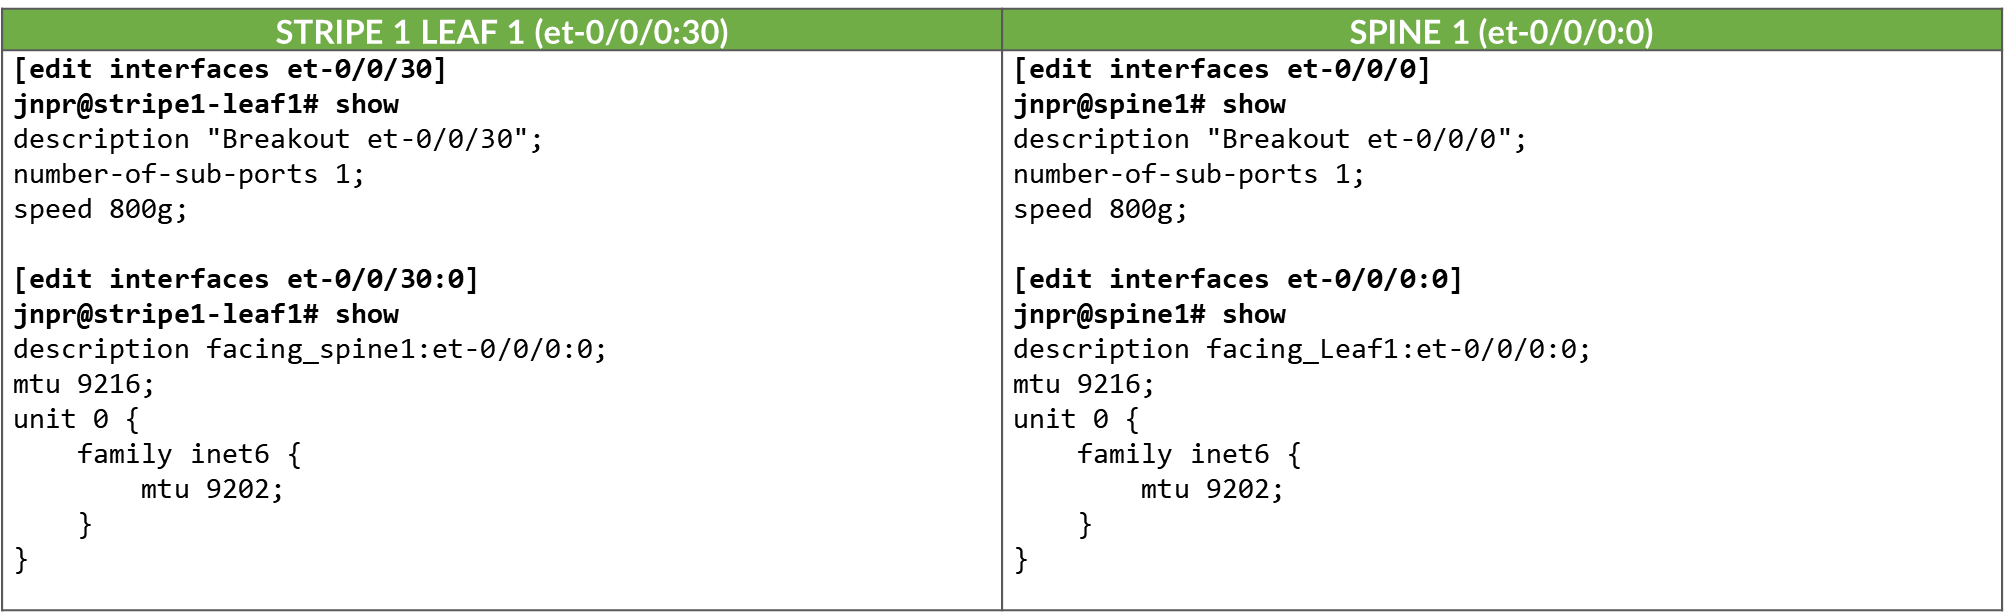
Enabling IPv6 on an interface automatically assigns a link-local IPv6 address. The switch autogenerates link local addresses for the interfaces using the EUI-64 address format (based on the interface’s MAC address), as shown in Table 21.
Table 21. Spine and Leaf IPv6-Enabled Interface Link Local Addresses
| LEAF NODE INTERFACE | LEAF NODE IPv6 ADDRESS | SPINE NODE INTERFACE | SPINE IPv6 ADDRESS |
|---|---|---|---|
| Stripe 1 Leaf 1 - et-0/0/30:0 | fe80::9e5a:80ff:fec1:ae00/64 | Spine 1 – et-0/0/0:0 | fe80::9e5a:80ff:feef:a28f/64 |
| Stripe 1 Leaf 1 - et-0/0/31:0 | fe80::9e5a:80ff:fec1:ae08/64 | Spine 2 – et-0/0/0:0 | fe80::5a86:70ff:fe7b:ced5/64 |
| Stripe 1 Leaf 1 - et-0/0/32:0 | fe80::9e5a:80ff:fec1:af00/64 | Spine 3 – et-0/0/0:0 | fe80::5a86:70ff:fe78:e0d5/64 |
| Stripe 1 Leaf 1 - et-0/0/33:0 | fe80::9e5a:80ff:fec1:af08/64 | Spine 4 – et-0/0/0:0 | fe80::5a86:70ff:fe79:3d5/64 |
| Stripe 1 Leaf 2 - et-0/0/30:0 | fe80::5a86:70ff:fe79:dad5/64 | Spine 1 – et-0/0/1:0 | fe80::9e5a:80ff:feef:a297/64 |
| Stripe 1 Leaf 2 - et-0/0/31:0 | fe80::5a86:70ff:fe79:dadd/64 | Spine 2 – et-0/0/1:0 | fe80::5a86:70ff:fe7b:cedd/64 |
| Stripe 1 Leaf 2 - et-0/0/32:0 | fe80::5a86:70ff:fe79:dbd5/64 | Spine 3 – et-0/0/1:0 | fe80::5a86:70ff:fe78:e0dd/64 |
| Stripe 1 Leaf 2 - et-0/0/33:0 | fe80::5a86:70ff:fe79:dbdd/64 | Spine 4 – et-0/0/1:0 | fe80::5a86:70ff:fe79:3dd/64 |
|
. . . |
These addresses need to be advertised through standard router advertisements as part of the IPv6 Neighbor Discovery process to allow the leaf and spine nodes to then establish BGP sessions between them. Router advertisement must be enabled on all the interfaces between the leaf and spine nodes as shown:
Table 22. IPv6 Router Advertisement on Leaf and Spine
Interfaces
To verify that router advertisements are being sent you can use:show IPv6
router-advertisement interface <interface> and show IPv6 neighbors
Example:
              jnpr@stripe1-leaf1> show IPv6 router-advertisement interface et-0/0/30:0
Interface: et-0/0/30:0.0
  Advertisements sent: 4, last sent 00:02:28 ago
  Solicits sent: 1, last sent 00:08:06 ago
  Solicits received: 0
  Advertisements received: 3
  Solicited router advertisement unicast: Disable
  IPv6 RA Preference: DEFAULT/MEDIUM
  Passive mode: Disable
  Upstream mode: Disable
  Downstream mode: Disable
  Proxy blackout timer: Not Running
  Advertisement from fe80::9e5a:80ff:feef:a28f, heard 00:01:57 ago
    Managed: 0
    Other configuration: 0
    Reachable time: 0 ms
    Default lifetime: 1800 sec
    Retransmit timer: 0 ms
    Current hop limit: 64
jnpr@stripe1-leaf1> show IPv6 neighbors
IPv6 Address    Linklayer Address  State       Exp   Rtr  Secure  Interface
fe80::5a86:70ff:fe78:e0d5       58:86:70:78:e0:d5  reachable   11    yes  no      et-0/0/31:0.0
fe80::5a86:70ff:fe79:3d5        58:86:70:79:03:d5  reachable   23    yes  no      et-0/0/33:0.0
fe80::5a86:70ff:fe7b:ced5       58:86:70:7b:ce:d5  reachable   13    yes  no      et-0/0/32:0.0
fe80::9e5a:80ff:feef:a28f       9c:5a:80:ef:a2:8f  reachable   25    yes  no      et-0/0/30:0.0
Total entries: 4
The loopback interface IPv6 addresses and the Autonomous System numbers for all devices in the fabric are included in table 23:
Table 23. Spine and Leaf Loopback Addresses and ASNs
| LEAF NODE INTERFACE | lo0.0 IPv6 ADDRESS | Local AS # |
|---|---|---|
| Stripe 1 Leaf 1 | FC00:10:0:1::1/128 | 201 |
| Stripe 1 Leaf 2 | FC00:10:0:1::2/128 | 202 |
| Stripe 1 Leaf 3 | FC00:10:0:1::3/128 | 203 |
| Stripe 1 Leaf 4 | FC00:10:0:1::4/128 | 204 |
| Stripe 1 Leaf 5 | FC00:10:0:1::5/128 | 205 |
| Stripe 1 Leaf 6 | FC00:10:0:1::6/128 | 206 |
| Stripe 1 Leaf 7 | FC00:10:0:1::7/128 | 207 |
| Stripe 1 Leaf 8 | FC00:10:0:1::8/128 | 208 |
| Stripe 2 Leaf 1 | FC00:10:0:1::9/128 | 209 |
| Stripe 2 Leaf 2 | FC00:10:0:1::10/128 | 210 |
|
. . . |
||
| SPINE1 | FC00:10:0::1/128 | 101 |
| SPINE2 | FC00:10:0::2/128 | 102 |
| SPINE3 | FC00:10:0::3/128 | 103 |
| SPINE4 | FC00:10:0::4/128 | 104 |
Table 24. Spine and Leaf Loopback Address Configuration 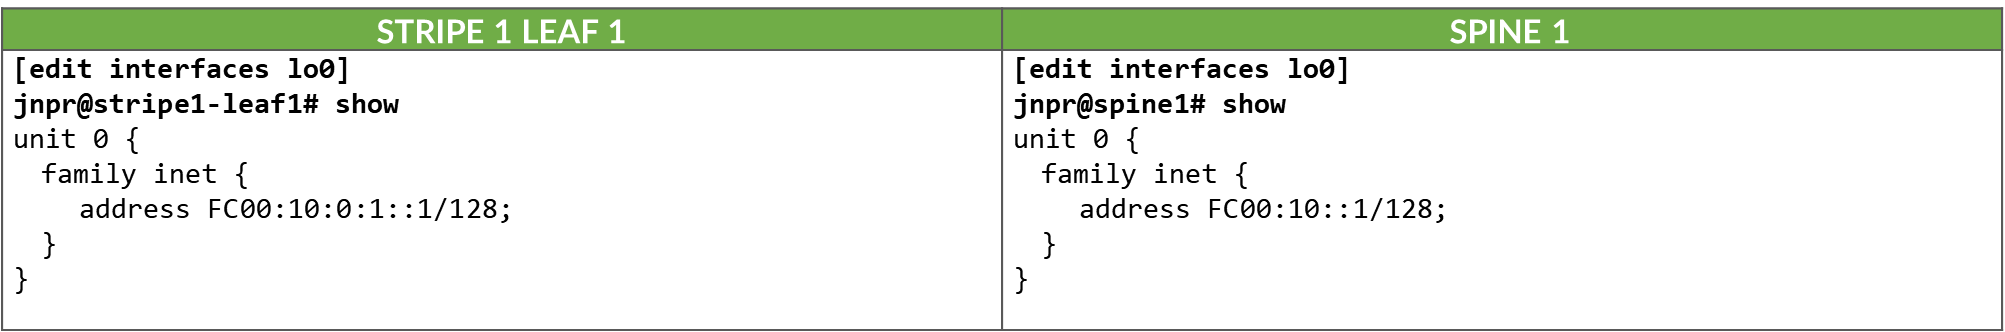
Recommended MTU
Configure the MTU consistently across the fabric and make sure that the MTU of the server->leaf links does not exceed the MTU of the leaf->spine links considering the extra overhead of the VXLAN encapsulation.
VXLAN Overhead Calculation
For IPv6, the MTU can also be calculated as:
Table 26 VXLAN Overhead Calculation
| HEADER | BYTES |
|---|---|
| Outer Ethernet | 14 |
| Outer IP (IPv6) | 40 |
| UDP | 8 |
| VXLAN | 8 |
| Total | 70 bytes |
Recommended MTU Strategy
Table 27. Recommended MTU
| LINK TYPE | MTU |
|---|---|
| Server ↔ Leaf | 9000 |
| Leaf ↔ Spine IPv6 | > 9070 |
It is important to keep in mind that RoCEv2 message sizes are still limited by the RDMA MTU reported by ibv_devinfo
jnpr@MI300-01:~/SCRIPTS$ ibv_devinfo -d bnxt_re0
hca_id: bnxt_re0
        transport:              InfiniBand (0)
        fw_ver:                 230.2.49.0
        node_guid:      7ec2:55ff:febd:75d0
        sys_image_guid:         7ec2:55ff:febd:75d0
        vendor_id:              0x14e4
        vendor_part_id:         5984
        hw_ver:                 0x1D42
        phys_port_cnt:          1
                port:   1
                        state:          PORT_ACTIVE (4)
                         max_mtu:               4096 (5)
                         active_mtu:            4096 (5)
                        sm_lid:                 0
                        port_lid:                       0
                        port_lmc:               0x00
                        link_layer:                     Ethernet
Table 28. MTU Types: Ownership and Functional Role
| MTU TYPE | OWNER | PURPOSE |
|---|---|---|
|
Interface MTU (e.g. 9000) ifconfig, ip |
Linux network stack | Defines the max L3/IP packet size |
|
RDMA MTU (e.g. 4096) ibv_devinfo |
RDMA stack | Defines the max RDMA message size per Work Queue Element (WQE) |
The RDMA MTU can be configured at the verbs level, and it’s negotiated during QP (Queue Pair) setup. You cannot override it by just setting the NIC's MTU to a higher value, but you would need to use low-level tools or RDMA apps.
Some performance tools such as ib_send_bw, ib_write_bw (via -m flag). For example:
ib_write_bw -m 1024 # sets RDMA MTU to 1024 bytes
ib_write_bw -m 4096 # sets RDMA MTU to 4096 (max allowed according to the output of ibv_devinfo shown before)
RDMA MTU must be ≤ Interface MTU – encapsulation overhead
IPv6 GPU Backend Fabric Underlay, using BGP Neighbor Discovery
Refer to Configure BGP Unnumbered EVPN Fabric | Juniper Networks for more information.
The underlay EBGP sessions are configured between the leaf and spine nodes to use peer auto-discovery, and are configured to advertise these loopback interfaces, as shown in the example between Stripe1 Leaf 1 and Spine 1 below:
Table 29. GPU Backend Fabric: BGP Underlay with Peer Auto-Discovery Configuration
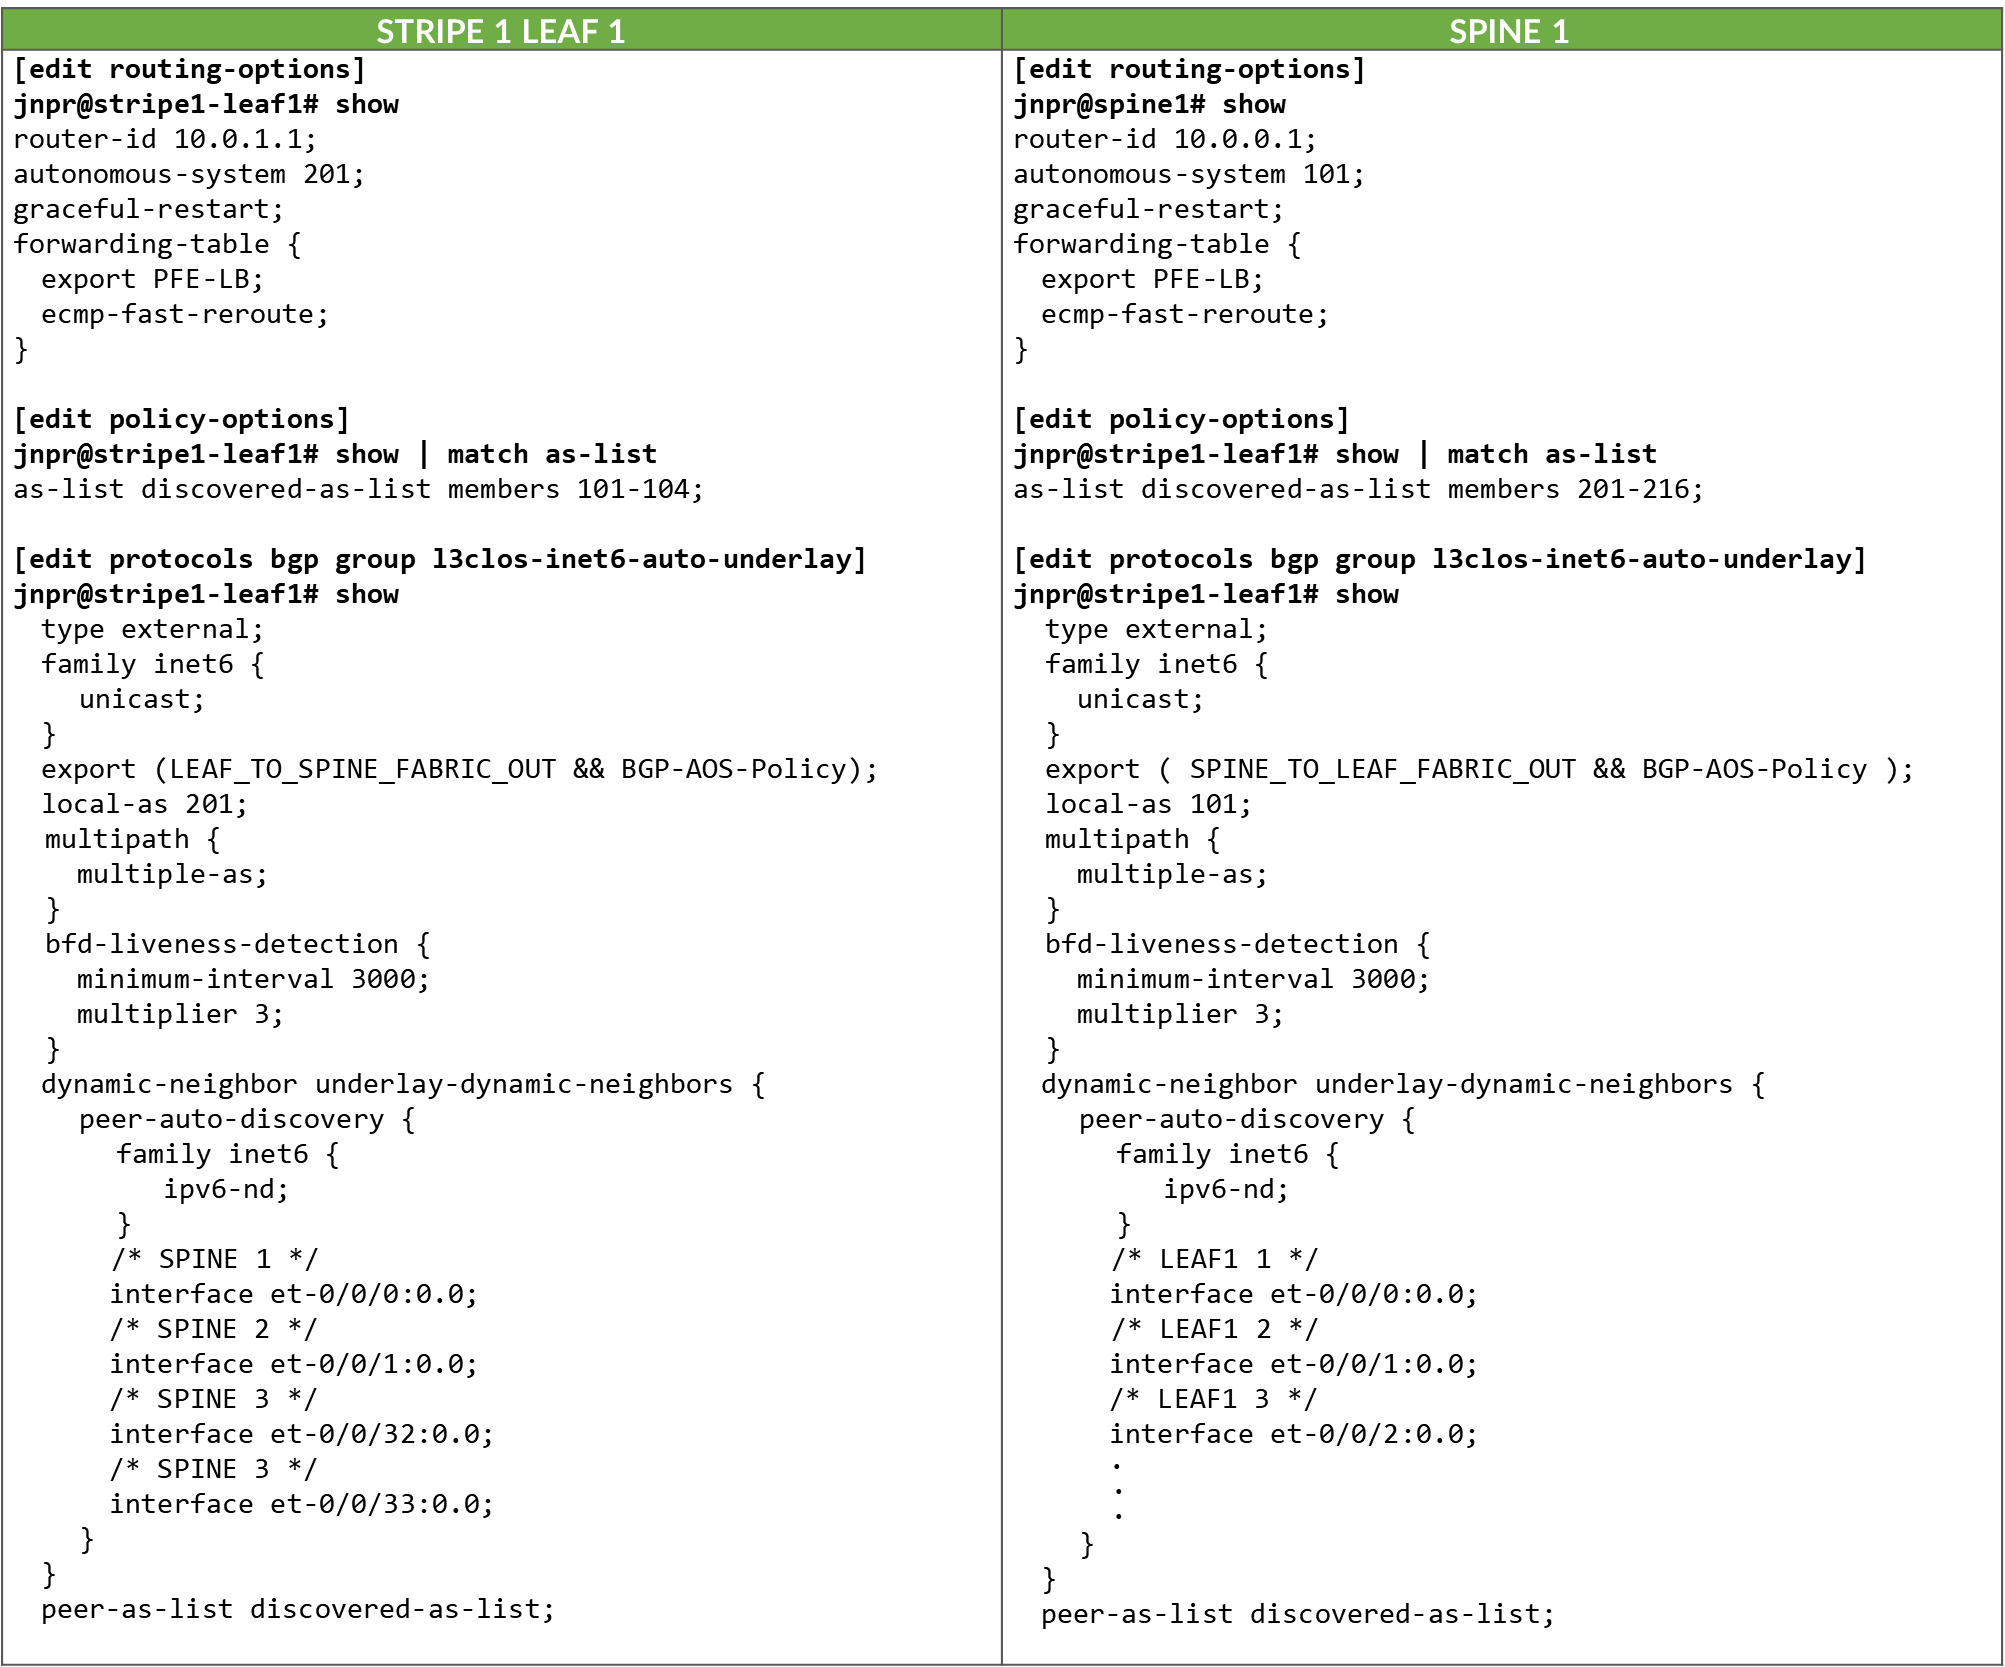
To configure peer auto discovery, the dynamic-neighbor named underlay-dynamic-neighbors, under BGP group l3clos-inet6-auto-underlay, specifies the interfaces where auto discovery is permitted. This replaces the neighbor a.b.c.d commands that would statically configure the neighbors.
The family inet6 IPv6-nd statement enables the use of IPv6 Neighbor Discovery to dynamically determine the addresses of neighbors with which to establish BGP sessions. To control and secure dynamic peer formation, a peer-as-list (discovered-as-list) is configured, restricting peering to neighbors whose autonomous system numbers fall within the defined range of AS 101–104.
The family inet6 unicast statements configure the sessions to advertise IPv6 prefixes to support the IPv6 overlays.
The BGP sessions are also configured with multipath multiple-as, allowing multiple paths (even with different AS paths) to be considered for ECMP (Equal-Cost Multi-Path) routing. BFD (Bidirectional Forwarding Detection) is additionally enabled to accelerate convergence in case of link or neighbor failures.
You can check that the sessions have been established using:
show bgp summary group <group-name>
Example:
jnpr@stripe1-leaf1> show bgp summary group l3clos-inet6-auto-underlay
fe80::5a86:70ff:fe78:e0d5%et-0/0/31:0.0         102        201        196       0       0     1:29:35 Establ
  inet6.0: 4/4/4/0
fe80::5a86:70ff:fe79:3d5%et-0/0/33:0.0          104        201        196       0       0     1:29:15 Establ
  inet6.0: 4/4/4/0
fe80::5a86:70ff:fe7b:ced5%et-0/0/32:0.0         103        201        196       0       0     1:29:21 Establ
  inet6.0: 4/4/4/0
fe80::9e5a:80ff:feef:a28f%et-0/0/30:0.0         101        202        197       0       0     1:29:30 Establ
  inet6.0: 4/4/4/0
Notice that when BGP sessions are established using link-local addresses Junos
displays the neighbor address along with the interface scope (e.g.
fe80::5a86:70ff:fe78:e0d5%et-0/0/1:0.0). The scope identifier (the part after the
%) is necessary because the same link-local address (fe80::/10) could exist on multiple
interfaces. The device must know which interface to use to send packets to that neighbor.
Thus, after peer discovery is completed, the
show bgp summary
output lists the neighbor using the format:
IPv6_link-local_address%interface-name.
You can check details about discovered neighbors using:
show bgp neighbor
        auto-discovered <peer-id>
Example:
jnpr@stripe1-leaf1> show bgp neighbor auto-discovered fe80::5a86:70ff:fe78:e0d5%et-0/0/31:0.0
Peer: fe80::5a86:70ff:fe78:e0d5%et-0/0/31:0.0+179 AS 102 Local: fe80::9e5a:80ff:fec1:ae08%et-0/0/31:0.0+53984 AS 201
  Group: l3clos-inet6-auto-underlay Routing-Instance: master
  Forwarding routing-instance: master
  Type: External    State: Established    Flags: <Sync PeerAsList AutoDiscoveredNdp>
  Last State: OpenConfirm   Last Event: RecvKeepAlive
  Last Error: None
  Export: [ (LEAF_TO_SPINE_FABRIC_OUT && BGP-AOS-Policy) ]
  Options: <GracefulRestart AddressFamily Multipath LocalAS Refresh>
  Options: <MultipathAs BfdEnabled>
  Options: <GracefulShutdownRcv>
  Address families configured: inet6-unicast
  Holdtime: 90 Preference: 170
  Graceful Shutdown Receiver local-preference: 0
  Local AS: 201 Local System AS: 201
  Number of flaps: 0
  Receive eBGP Origin Validation community: Reject
  Peer ID: 10.0.0.2        Local ID: 10.0.1.1          Active Holdtime: 90
  Keepalive Interval: 30         Group index: 0    Peer index: 0    SNMP index: 30
  I/O Session Thread: bgpio-0 State: Enabled
  BFD: enabled, up
  Local Interface: et-0/0/1:0.0
  NLRI for restart configured on peer: inet6-unicast
  NLRI advertised by peer: inet6-unicast
  NLRI for this session: inet6-unicast
  Peer supports Refresh capability (2)
  Restart time configured on the peer: 120
  Stale routes from peer are kept for: 300
  Restart time requested by this peer: 120
  Restart flag received from the peer: Notification
  NLRI that peer supports restart for: inet6-unicast
  NLRI peer can save forwarding state: inet6-unicast
  NLRI that peer saved forwarding for: inet6-unicast
  NLRI that restart is negotiated for: inet6-unicast
  NLRI of received end-of-rib markers: inet6-unicast
  NLRI of all end-of-rib markers sent: inet6-unicast
  Peer does not support LLGR Restarter functionality
  Peer supports 4 byte AS extension (peer-as 102)
  Peer does not support Addpath
  NLRI(s) enabled for color nexthop resolution: inet6-unicast
  Table inet6.0 Bit: 20000
    RIB State: BGP restart is complete
    Send state: in sync
    Active prefixes:              4
    Received prefixes:            4
    Accepted prefixes:            4
    Suppressed due to damping:    0
    Advertised prefixes:          1
  Last traffic (seconds): Received 20   Sent 24   Checked 5788
  Input messages:  Total 216    Updates 5       Refreshes 0     Octets 4535
  Output messages: Total 212    Updates 1       Refreshes 0     Octets 4125
  Output Queue[1]: 0            (inet6.0, inet6-unicast)
  Trace options:  all
  Trace file: /var/log//bgp size 131072 files 10
To verify the operation of BFD for the BGP sessions use:
show bfd session
Example:
jnpr@stripe1-leaf1> show bfd session
                                                  Detect   Transmit
Address                   State     Interface      Time     Interval  Multiplier
fe80::5a86:70ff:fe78:e0d5 Up       et-0/0/31:0.0   9.000     3.000        3
fe80::5a86:70ff:fe79:3d5  Up       et-0/0/33:0.0   9.000     3.000        3
fe80::5a86:70ff:fe7b:ced5 Up       et-0/0/32:0.0   9.000     3.000        3
fe80::9e5a:80ff:feef:a28f Up       et-0/0/30:0.0   9.000     3.000        3
8 sessions, 8 clients
Cumulative transmit rate 2.7 pps, cumulative receive rate 2.7 pps
To control the propagation of routes, and make sure the loopback interface addresses are advertised, export policies are applied to these EBGP sessions as shown in the example in Table 30.
Table 30. Export policy example IPv6 Underlay with auto discovery
These policies ensure loopback reachability without advertising unnecessary routes.
On the spine nodes, routes are exported only if they are accepted by both the SPINE_TO_LEAF_FABRIC_OUT and BGP-AOS-Policy export policies.
- The SPINE_TO_LEAF_FABRIC_OUT policy has no match conditions and accepts all routes unconditionally, tagging them with the FROM_SPINE_FABRIC_TIER community (0:15).
- The BGP-AOS-Policy accepts BGP-learned routes as well as any routes accepted by the nested AllPodNetworks policy.
- The AllPodNetworks policy, in turn, matches directly connected IPv6 routes and tags them with the DEFAULT_DIRECT_V6 community (1:20008 and 21001:26000 on Spine1).
As a result, each spine advertises both its directly connected routes (including its loopback interface) and any routes it has received from other leaf nodes.
You can
verify that the expected routes are being advertised by the spine node using: show
route advertising-protocol bgp <peer-id> table inet6.0
Example:
The following example shows the routes advertised to Stripe 1 Leaf 1 by Spine 1 which correspond to the loopback interface addresses of itself, as well as Stripe1 Leaf 2, Stripe 2 Leaf 1, and Stripe 2 Leaf 2.
jnpr@spine1> show route advertising-protocol bgp fe80::9e5a:80ff:fec1:ae00%et-0/0/30:0.0 table inet6.0 inet6.0: 11 destinations, 11 routes (11 active, 0 holddown, 0 hidden) Restart Complete Prefix Nexthop MED Lclpref AS path * fc00:10::1/128 Self I * fc00:10:0:1::2/128 Self 202 I * fc00:10:0:1::9/128 Self 209 I * fc00:10:0:1::10/128 Self 210 I
To verify routes are received by the Leaf nodes use: show route
receive-protocol bgp <peer-id> table inet6.0
Example:
jnpr@stripe1-leaf1> show route receive-protocol bgp fe80::5a86:70ff:fe78:e0d5%et-0/0/1:0.0 table inet6.0 inet6.0: 14 destinations, 23 routes (14 active, 0 holddown, 0 hidden) Restart Complete Prefix Nexthop MED Lclpref AS path * fc00:10::1/128 fe80::9e5a:80ff:feef:a28f 101 I fc00:10:0:1::2/128 fe80::9e5a:80ff:feef:a28f 101 202 I fc00:10:0:1::9/128 fe80::9e5a:80ff:feef:a28f 101 209 I fc00:10:0:1::10/128 fe80::9e5a:80ff:feef:a28f 101 210 I
On the leaf nodes, routes are exported only if they are accepted by both the LEAF_TO_SPINE_FABRIC_OUT and BGP-AOS-Policy export policies.
- The LEAF_TO_SPINE_FABRIC_OUT policy accepts all routes except those learned via BGP that are tagged with the FROM_SPINE_FABRIC_TIER community (0:15). These routes are explicitly rejected to prevent re-advertisement of spine-learned routes back into the spine layer. As described earlier, spine nodes tag all routes they advertise to leaf nodes with this community to facilitate this filtering logic.
- The BGP-AOS-Policy accepts all routes allowed by the nested AllPodNetworks policy, which matches directly connected IPv6 routes and tags them with the DEFAULT_DIRECT_V4 community (5:20007 and 21001:26000 for Stripe1-Leaf1).
- As a result, leaf nodes will advertise only their directly connected interface routes, including their loopback interfaces, to the spines.
You can verify that the expected routes are being advertised by the spine node using:
show
          route advertising-protocol bgp <peer-id> table inet6.0
Example:
The following example shows the routes advertised to Spine 1 by Stripe 1 Leaf 1.
jnpr@stripe1-leaf1> show route advertising-protocol bgp fe80::5a86:70ff:fe78:e0d5%et-0/0/30:0.0 table inet6.0
inet6.0: 14 destinations, 23 routes (14 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
* fc00:10:0:1::1/128      Self                                    I
To verify routes are received by the spine node, use: show route
receive-protocol bgp <peer-id> table inet6.0
Example:
jnpr@spine1> show route receive-protocol bgp fe80::9e5a:80ff:fec1:ae00%et-0/0/0:0.0 table inet6.0
inet6.0: 11 destinations, 11 routes (11 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
* fc00:10:0:1::1/128      fe80::9e5a:80ff:fec1:ae00               201 I
IPv6 GPU Backend Fabric Overlay
When EVPN Type 5 is used to implement L3 tenant isolation across a VXLAN fabric, multiple routing tables are instantiated on each participating leaf node. These tables are responsible for managing control-plane separation, enforcing tenant boundaries, and supporting the overlay forwarding model. Each routing instance (VRF) creates its own set of routing and forwarding tables, in addition to the global and EVPN-specific tables used for fabric-wide communication. These tables are listed in Table 31.
Table 31. Routing and Forwarding Tables for EVPN Type 5
| TABLE | DESCRIPTON |
|---|---|
| bgp.evpn.0 |
Holds EVPN route information received via BGP, including Type 5 (IP Prefix) routes and other EVPN route types. This is the control plane source for EVPN-learned routes |
| <tenant-name>.evpn.0 | The tenant-specific EVPN table. |
| <tenant-name>.inet.0 |
The tenant-specific IPv4 unicast routing table. Contains directly connected and EVPN-imported Type 5 prefixes for that tenant. Used for routing data plane traffic. |
When routing instances are created for the tenants, separate routing domains (tenant-name.<tenant-name>.inet6.0) are created, providing full route and traffic isolation across the EVPN/VXLAN fabric.
The protocol next-hop (loopback interface or remote leaf) on each EVPN route is resolved in inet6.0. Then the route is added to the bgp.evpn.0 table. The routes are then imported into <tenant>.evpn.0 and <tenant>.inet6.0, based on route-targets.
The Overlay BGP Sessions between the leaf and spine nodes are statically configured (not auto discovered) using the loopback interfaces global IPv6 addresses, which were advertised by the Underlay BGP sessions.
As an example, consider the configuration between Stripe1 Leaf 1 and Spine 1.
Table 32. GPU Backend Fabric Overlay Using IPv6 Loopback
Addresses
The sessions use family evpn signaling to enable EVPN route exchange. The multihop ttl 1 statement allows EBGP sessions to be established between the loopback interfaces.
As with the underlay BGP sessions, these sessions are configured with multipath multiple-as, allowing multiple EVPN paths with different AS paths to be considered for ECMP (Equal-Cost Multi-Path) routing. BFD (Bidirectional Forwarding Detection) is also enabled to improve convergence time in case of failures.
The no-nexthop-change knob on the spine nodes is used to preserve the original next-hop address, which is critical in EVPN for ensuring that the remote VTEP can be reached directly. The vpn-apply-export statement is included to ensure that the export policies are evaluated for VPN address families, such as EVPN, allowing fine-grained control over which routes are advertised to each peer.
You can check that the sessions have been established using: show bgp summary group <group-name>
Example:
jnpr@stripe1-leaf1> show bgp summary group l3clos-inet6-auto-overlay
fc00:10:0:1::1          201        118        127       0       0       52:58 Establ
  bgp.evpn.0: 4/4/4/0
fc00:10:0:1::2          202        119        128       0       0       53:01 Establ
  bgp.evpn.0: 4/4/4/0
fc00:10:0:1::9          209        119        127       0       0       53:10 Establ
  bgp.evpn.0: 4/4/4/0
fc00:10:0:1::10         210         81         81       0       3       35:28 Establ
  bgp.evpn.0: 4/4/4/0
To verify the operation of BFD for the BGP sessions use: show bfd session
Example:
jnpr@stripe1-leaf1> show bfd session
                                                  Detect   Transmit
Address                  State     Interface      Time     Interval  Multiplier
fc00:10::1               Up                       9.000     3.000        3
fc00:10::2               Up                       9.000     3.000        3
fc00:10::3               Up                       9.000     3.000        3
fc00:10::4               Up                       9.000     3.000        3
8 sessions, 8 clients
Cumulative transmit rate 2.7 pps, cumulative receive rate 2.7 pps
You can check details about discovered neighbors using: show bgp neighbor <peer-id>
Example:
jnpr@stripe1-leaf1> show bgp neighbor fc00:10::1
Peer: fc00:10::1+48522 AS 101  Local: fc00:10:0:1::1+179 AS 201
  Description: facing_spine1-evpn-overlay
  Group: l3clos-inet6-auto-overlay Routing-Instance: master
  Forwarding routing-instance: master
  Type: External    State: Established    Flags: <Sync>
  Last State: OpenConfirm   Last Event: RecvKeepAlive
  Last Error: None
  Export: [ (LEAF_TO_SPINE_EVPN_OUT && EVPN_EXPORT) ]
  Options: <Multihop LocalAddress GracefulRestart Ttl AddressFamily PeerAS Multipath Rib-group Refresh>
  Options: <VpnApplyExport MultipathAs BfdEnabled>
  Options: <GracefulShutdownRcv>
  Address families configured: evpn
  Local Address: fc00:10:0:1::1 Holdtime: 90 Preference: 170
  Graceful Shutdown Receiver local-preference: 0
  Number of flaps: 0
  Receive eBGP Origin Validation community: Reject
  Peer ID: 10.0.0.1        Local ID: 10.0.1.1          Active Holdtime: 90
  Keepalive Interval: 30         Group index: 2    Peer index: 3    SNMP index: 61
  I/O Session Thread: bgpio-0 State: Enabled
  BFD: enabled, up
  NLRI for restart configured on peer: evpn
  NLRI advertised by peer: evpn
  NLRI for this session: evpn
  Peer supports Refresh capability (2)
  Restart time configured on the peer: 120
  Stale routes from peer are kept for: 300
  Restart time requested by this peer: 120
  Restart flag received from the peer: Notification
  NLRI that peer supports restart for: evpn
  NLRI peer can save forwarding state: evpn
  NLRI that peer saved forwarding for: evpn
  NLRI that restart is negotiated for: evpn
  NLRI of received end-of-rib markers: evpn
  NLRI of all end-of-rib markers sent: evpn
  Peer does not support LLGR Restarter functionality
  Peer supports 4 byte AS extension (peer-as 101)
  Peer does not support Addpath
  NLRI(s) enabled for color nexthop resolution: evpn
  Table bgp.evpn.0 Bit: 40000
    RIB State: BGP restart is complete
    RIB State: VPN restart is complete
    Send state: in sync
    Active prefixes:              0
    Received prefixes:            12
    Accepted prefixes:            12
    Suppressed due to damping:    0
    Advertised prefixes:          4
  Table Tenant-1.evpn.0
    RIB State: BGP restart is complete
    RIB State: VPN restart is complete
    Send state: not advertising
    Active prefixes:              0
    Received prefixes:            4
    Accepted prefixes:            4
    Suppressed due to damping:    0
  Last traffic (seconds): Received 14   Sent 11   Checked 3980
  Input messages:  Total 158    Updates 16      Refreshes 0     Octets 6079
  Output messages: Total 146    Updates 1       Refreshes 0     Octets 3105
  Output Queue[3]: 0            (bgp.evpn.0, evpn)
To control the propagation of routes, export policies are applied to these EBGP sessions as shown in the example in Table 33.
Table 33. Export Policy example to advertise EVPN routes over
IPv6 overlay 
These policies are simpler in structure and are intended to enable end-to-end EVPN reachability between tenant GPUs, while preventing route loops within the overlay.
Routes will only be advertised if EVPN routing-instances have been created, as described in the Per Tenant IP-VRF Routing Instances section.
On the spine nodes, routes are exported if they are accepted by the SPINE_TO_LEAF_EVPN_OUT policy.
- The SPINE_TO_LEAF_EVPN_OUT policy has no match conditions and accepts all routes. It tags each exported route with the FROM_SPINE_EVPN_TIER community (0:14).
As a result, the spine nodes export EVPN routes received from one leaf to all other leaf nodes, allowing tenant-to-tenant communication across the fabric.
You can verify that the expected routes are being advertised by the spine node
using:show route advertising-protocol bgp <peer-id> table
bgp.evpn.0show route advertising-protocol bgp <peer-id>
match-prefix <prefix>
Example:
jnpr@spine1> show route advertising-protocol bgp FC00:10:0:1::1 table bgp.evpn.0
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
Prefix Nexthop MED Lclpref AS path
5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
* fc00:10:0:1::2 202 I
5:10.0.1.2:2002::0::fc00:200:2:1::::64/248
* fc00:10:0:1::2 202 I
5:10.0.1.2:2002::0::fc00:200:2:2::::64/248
* fc00:10:0:1::2 202 I
5:10.0.1.2:2002::0::fc00:200:2:3::::64/248
* fc00:10:0:1::2 202 I
5:10.0.1.9:2001::0::fc00:100:2:1::::64/248
* fc00:10:0:1::9 209 I
5:10.0.1.9:2001::0::fc00:200:1:9::::64/248
* fc00:10:0:1::9 209 I
5:10.0.1.9:2001::0::fc00:200:1:10::::64/248
* fc00:10:0:1::9 209 I
5:10.0.1.9:2001::0::fc00:200:1:11::::64/248
* fc00:10:0:1::9 209 I
5:10.0.1.10:2002::0::fc00:100:2:2::::64/248
* fc00:10:0:1::10 210 I
5:10.0.1.10:2002::0::fc00:200:2:9::::64/248
* fc00:10:0:1::10 210 I
5:10.0.1.10:2002::0::fc00:200:2:10::::64/248
* fc00:10:0:1::10 210 I
5:10.0.1.10:2002::0::fc00:200:2:11::::64/248
* fc00:10:0:1::10 210 I
jnpr@spine1> show route advertising-protocol bgp FC00:10:0:1::1 match-prefix 5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
Prefix Nexthop MED Lclpref AS path
5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
* fc00:10:0:1::2 202 I
jnpr@spine1> show route advertising-protocol bgp FC00:10:0:1::1 match-prefix 5:10.0.1.2:2002::0::fc00:100:1:2::::64/248 extensive
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
* 5:10.0.1.2:2002::0::fc00:100:1:2::::64/248 (1 entry, 1 announced)
BGP group l3clos-inet6-auto-overlay type External
Route Distinguisher: 10.0.1.2:2002
Route Label: 20002
Overlay gateway address: ::
Nexthop: fc00:10:0:1::2
AS path: [101] 202 I
Communities: 0:14 5:20008 21002:26000 target:20002:1 encapsulation:vxlan(0x8) router-mac:58:86:70:79:df:db
jnpr@spine1> show route advertising-protocol bgp FC00:10:0:1::1 match-prefix 5:10.0.1.9:2001::0::fc00:200:1:9::::64/248
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
Prefix Nexthop MED Lclpref AS path
5:10.0.1.9:2001::0::fc00:200:1:9::::64/248
* fc00:10:0:1::9 209 I
jnpr@spine1> show route advertising-protocol bgp FC00:10:0:1::1 match-prefix 5:10.0.1.9:2001::0::fc00:200:1:9::::64/248 extensive
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
* 5:10.0.1.9:2001::0::fc00:200:1:9::::64/248 (1 entry, 1 announced)
BGP group l3clos-inet6-auto-overlay type External
Route Distinguisher: 10.0.1.9:2001
Route Label: 20001
Overlay gateway address: ::
Nexthop: fc00:10:0:1::9
AS path: [101] 209 I
Communities: 0:14 5:20008 21001:26000 target:20001:1 encapsulation:vxlan(0x8) router-mac:58:86:70:7b:10:dbThe leaf nodes receive the routes and first install them in the bgp.evpn.0 routing table
which can be verified using:show route receive-protocol bgp <peer-id> table
bgp.evpn.0
Example:
jnpr@stripe1-leaf1> show route receive-protocol bgp fc00:10::1 table bgp.evpn.0
bgp.evpn.0: 16 destinations, 52 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
Prefix Nexthop MED Lclpref AS path
5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
fc00:10:0:1::2 101 202 I
5:10.0.1.2:2002::0::fc00:200:2:1::::64/248
fc00:10:0:1::2 101 202 I
5:10.0.1.2:2002::0::fc00:200:2:2::::64/248
fc00:10:0:1::2 101 202 I
5:10.0.1.2:2002::0::fc00:200:2:3::::64/248
fc00:10:0:1::2 101 202 I
5:10.0.1.9:2001::0::fc00:100:2:1::::64/248
fc00:10:0:1::9 101 209 I
5:10.0.1.9:2001::0::fc00:200:1:9::::64/248
fc00:10:0:1::9 101 209 I
5:10.0.1.9:2001::0::fc00:200:1:10::::64/248
fc00:10:0:1::9 101 209 I
5:10.0.1.9:2001::0::fc00:200:1:11::::64/248
fc00:10:0:1::9 101 209 I
5:10.0.1.10:2002::0::fc00:100:2:2::::64/248
fc00:10:0:1::10 101 210 I
5:10.0.1.10:2002::0::fc00:200:2:9::::64/248
fc00:10:0:1::10 101 210 I
5:10.0.1.10:2002::0::fc00:200:2:10::::64/248
fc00:10:0:1::10 101 210 I
5:10.0.1.10:2002::0::fc00:200:2:11::::64/248
fc00:10:0:1::10 101 210 I
jnpr@stripe1-leaf1> show route receive-protocol bgp fc00:10::1 table bgp.evpn.0 match-prefix 5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
bgp.evpn.0: 16 destinations, 52 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
Prefix Nexthop MED Lclpref AS path
5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
fc00:10:0:1::2 101 202 I
jnpr@stripe1-leaf1> show route receive-protocol bgp fc00:10::1 table bgp.evpn.0 match-prefix 5:10.0.1.2:2002::0::fc00:100:1:2::::64/248 extensive
bgp.evpn.0: 16 destinations, 52 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
5:10.0.1.2:2002::0::fc00:100:1:2::::64/248 (4 entries, 0 announced)
Accepted
Route Distinguisher: 10.0.1.2:2002
Route Label: 20002
Overlay gateway address: ::
Nexthop: fc00:10:0:1::2
AS path: 101 202 I
Communities: 0:14 5:20008 21002:26000 target:20002:1 encapsulation:vxlan(0x8) router-mac:58:86:70:79:df:dbOn the leaf nodes, routes are exported if they are accepted by both the LEAF_TO_SPINE_EVPN_OUT and EVPN_EXPORT policies.
- The LEAF_TO_SPINE_EVPN_OUT policy rejects any BGP-learned routes that carry the FROM_SPINE_EVPN_TIER community (0:14). These routes are explicitly rejected to prevent re-advertisement of spine-learned routes back into the spine layer. As described earlier, spine nodes tag all routes they advertise to leaf nodes with this community to facilitate this filtering logic.
- The EVPN_EXPORT policy accepts all routes without additional conditions.
As a result, the leaf nodes export only locally originated EVPN routes for the directly connected interfaces between GPU servers and the leaf nodes. These routes are part of the tenant routing instances and are used to establish reachability between GPUs belonging to the same tenant.
You can verify that the expected routes are being advertised by the Leaf nodes using:
show route advertising-protocol bgp <peer-id> table
          bgp.evpn.0
show route advertising-protocol bgp <peer-id>
          match-prefix <prefix>
Example:
jnpr@stripe1-leaf1> show route advertising-protocol bgp FC00:10::1 table bgp.evpn.0
bgp.evpn.0: 16 destinations, 52 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
*                         Self                                    I
  5:10.0.1.1:2001::0::fc00:200:1:1::::64/248
*                         Self                                    I
  5:10.0.1.1:2001::0::fc00:200:1:2::::64/248
*                         Self                                    I
  5:10.0.1.1:2001::0::fc00:200:1:3::::64/248
*                         Self                                    I
jnpr@stripe1-leaf1> show route advertising-protocol bgp FC00:10::1 table bgp.evpn.0 match-prefix 5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
bgp.evpn.0: 16 destinations, 52 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
*                         Self                                    I
jnpr@stripe1-leaf1> show route advertising-protocol bgp FC00:10::1 table bgp.evpn.0 match-prefix 5:10.0.1.1:2001::0::fc00:100:1:1::::64/248 extensive
bgp.evpn.0: 16 destinations, 52 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
* 5:10.0.1.1:2001::0::fc00:100:1:1::::64/248 (1 entry, 1 announced)
 BGP group l3clos-inet6-auto-overlay type External
     Route Distinguisher: 10.0.1.1:2001
     Route Label: 20001
     Overlay gateway address: ::
     Nexthop: Self
     Flags: Nexthop Change
     AS path: [201] I
     Communities: 5:20008 21001:26000 target:20001:1 encapsulation:vxlan(0x8) router-mac:9c:5a:80:c1:b3:06
To verify routes are received by the spine nodes use: show route receive-protocol
bgp <peer-id> table bgp.evpn.0
Example:
jnpr@spine1> show route receive-protocol bgp fc00:10:0:1::1 table bgp.evpn.0
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
*                         fc00:10:0:1::1                          201 I
  5:10.0.1.1:2001::0::fc00:200:1:1::::64/248
*                         fc00:10:0:1::1                          201 I
  5:10.0.1.1:2001::0::fc00:200:1:2::::64/248
*                         fc00:10:0:1::1                          201 I
  5:10.0.1.1:2001::0::fc00:200:1:3::::64/248
*                         fc00:10:0:1::1                          201 I
jnpr@spine1> show route receive-protocol bgp fc00:10:0:1::1 match-prefix 5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
*                         fc00:10:0:1::1                          201 I
jnpr@spine1> show route receive-protocol bgp fc00:10:0:1::1 match-prefix 5:10.0.1.1:2001::0::fc00:100:1:1::::64/248 extensive
bgp.evpn.0: 16 destinations, 16 routes (16 active, 0 holddown, 0 hidden)
Restart Complete
* 5:10.0.1.1:2001::0::fc00:100:1:1::::64/248 (1 entry, 1 announced)
     Accepted
     Route Distinguisher: 10.0.1.1:2001
     Route Label: 20001
     Overlay gateway address: ::
     Nexthop: fc00:10:0:1::1
     AS path: 201 I
     Communities: 5:20008 21001:26000 target:20001:1 encapsulation:vxlan(0x8) router-mac:9c:5a:80:c1:b3:06
Tenants IP-VRF Routing Instances
Stripe 1 Leaf 1 and Stripe 1 Leaf 2 have been configured for Tenant-1 and Tenant-2 respectively as shown in Table 34. Stripe 2 Leaf 1 and Stripe 2 Leaf 2 are configured similarly.
Table 34. EVPN Routing-Instance for Tenant-1 and Tenant-2 Across
Stripe 1 and Stripe 2
Table 35. Policies Examples for Tenant-1 and Tenant-2 
Each routing instance is configured with the following key elements:
-
Interfaces:
The interfaces listed under each tenant VRF (e.g. et-0/0/0:0.0 and et-0/0/1:0.0) are explicitly added to the corresponding routing table. By placing these interfaces under the VRF, all routing decisions and traffic forwarding associated with them are isolated from other tenants and from the global routing table. Assigning an interface that connects a particular GPU to the leaf node effectively maps that GPU to a specific tenant, isolating it from GPUs assigned to other tenants.
-
Route-distinguisher (RD):
10.0.1.1:2001 and 10.0.1.1:2002 uniquely identify EVPN routes from Tenant-1 and Tenant-2, respectively. Even if both tenants use overlapping IP prefixes, the RD ensures their routes remain distinct in the BGP control plane. Although the GPU to leaf links use unique /32 prefixes, an RD is still required to advertise these routes over EVPN.
-
Route target (RT) community:
VRF targets 20001:1 and 20002:1 control which routes are exported from and imported into each tenant routing table. These values determine which routes are shared between VRFs that belong to the same tenant across the fabric and are essential for enabling fabric-wide tenant connectivity, for example, when a tenant has GPUs assigned to multiple servers across different stripes.
-
Protocols evpn parameters:
- The ip-prefix-routes controls how IP Prefix Routes (EVPN Type 5 routes) are advertised.
- The advertise direct-nexthop enables the leaf node to send IP prefix information using EVPN pure Type 5 routes, which includes a router MAC extended community. These routes include a Router MAC extended community, which allows the remote VTEP to resolve the next-hop MAC address without relying on Type 2 routes.
- The encapsulation vxlan indicates that the payload traffic for this tenant will be encapsulated using VXLAN. The same type of encapsulation must be used end to end.
- The VXLAN Network Identifier (VNI) acts as the encapsulation tag for traffic sent across the EVPN/VXLAN fabric. When EVPN Type 5 (IP Prefix) routes are advertised, the associated VNI is included in the BGP update. This ensures that remote VTEPs can identify the correct VXLAN segment for returning traffic to the tenant’s VRF.
- Unlike traditional use cases where a VNI maps to a single Layer 2 segment, in EVPN Type 5 the VNI represents the tenant-wide Layer 3 routing domain. All point-to-point subnets, such as the /32 links between GPU servers and the leaf, that belong to the same VRF are advertised with the same VNI.
In this configuration, VNIs 20001 and 20002 are mapped to the Tenant-1 and Tenant-2 VRFs, respectively. All traffic destined for interfaces in Tenant-1 will be forwarded using VNI 20001, and all traffic for Tenant-2 will use VNI 20002.
Notice that the same VNI for a specific tenant is configured on both Stripe1-Leaf1 and Stripe2-Leaf1.
-
Export Policy Logic
EVPN Type 5 routes from Tenant-1 are exported if they are accepted by the BGP-AOS-Policy-Tenant-1 export policy, which references a nested policy named AllPodNetworks-Tenant-1 (and the equivalent policies for Tenant-2)
- Policy BGP-AOS-Policy-Tenant-1 controls which prefixes from this VRF are allowed to be advertised into EVPN. It accepts any route that is permitted by the AllPodNetworks-Tenant-1 policy and explicitly rejects all other routes.
- Policy AllPodNetworks-Tenant-1 accepts directly connected IPv4 routes (family inet, protocol direct) that are part of the Tenant-1 VRF. It tags these routes with the TENANT-1 _COMMUNITY_V4 (5:20007 21002:26000 ) community before accepting them. All other routes are rejected.
As a result, only the directly connected IPv4 routes from the Tenant-1 (/32 links between GPU servers and the leaf) are exported as EVPN Type 5 routes.
To verify that the interfaces have been assigned to the correct routing instance and
installed in the correct tenant’s routing table use: show interfaces
routing-instance <tenant-name> terse
Example:
jnpr@stripe1-leaf1> show interfaces routing-instance Tenant-1 terse
Interface              Admin Link Proto     Local                 Remote
et-0/0/0:0.0            up    up   inet6    fc00:200:1:1::1/64
                                            fe80::9e5a:80ff:fec1:ae60/64
                                   multiservice
et-0/0/1:0.0            up    up   inet6    fc00:200:1:2::1/64
                                            fe80::9e5a:80ff:fec1:ae61/64
                                   multiservice
et-0/0/2:0.0            up    up   inet6    fc00:200:1:3::1/64
                                            fe80::9e5a:80ff:fec1:ae68/64
                                   multiservice
lo0.1                   up    up   inet6    fc00:100:1:1::1/64
                                            fe80::9e5a:80f0:c1:b2ff-->
jnpr@stripe1-leaf2> show interfaces routing-instance Tenant-2 terse
Interface               Admin Link Proto    Local                 Remote
et-0/0/0:0.0            up    up   inet6    fc00:200:2:1::1/64
                                            fe80::5a86:70ff:fe79:db35/64
                                   multiservice
et-0/0/1:0.0            up    up   inet6    fc00:200:2:2::1/64
                                            fe80::5a86:70ff:fe79:db36/64
                                   multiservice
et-0/0/2:0.0            up    up   inet6    fc00:200:2:3::1/64
                                            fe80::5a86:70ff:fe79:db3d/64
                                   multiservice
lo0.2                   up    up   inet6    fc00:100:1:2::1/64
                                            fe80::5a86:70f0:79:dfd4-->
You can also check the direct routes installed to the correspondent routing table using:
show route protocol direct table <tenant-name>.inet6.0
Example:
jnpr@stripe1-leaf1> show route protocol direct table Tenant-1.inet6.0
Tenant-1.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:1:1::/64  *[Direct/0] 01:02:26
                    >  via lo0.1
fc00:200:1:1::/64  *[Direct/0] 01:10:04
                    >  via et-0/0/12:0.0
fc00:200:1:2::/64  *[Direct/0] 01:10:04
                    >  via et-0/0/12:1.0
fc00:200:1:3::/64  *[Direct/0] 01:10:04
                    >  via et-0/0/13:0.0
fe80::9e5a:80f0:c1:b2ff/128
                   *[Direct/0] 03:22:19
                    >  via lo0.1
jnpr@stripe1-leaf2> show route protocol direct table Tenant-2.inet6.0
Tenant-2.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:1:2::/64  *[Direct/0] 00:24:41
                    >  via lo0.2
fc00:200:2:1::/64  *[Direct/0] 00:24:41
                    >  via et-0/0/12:0.0
fc00:200:2:2::/64  *[Direct/0] 00:24:41
                    >  via et-0/0/12:1.0
fc00:200:2:3::/64  *[Direct/0] 00:24:41
                    >  via et-0/0/13:0.0
fe80::5a86:70f0:79:dfd4/128
                   *[Direct/0] 00:24:41
                    >  via lo0.2
jnpr@stripe2-leaf1> show route protocol direct table Tenant-1.inet6.0
Tenant-1.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:2:1::/64  *[Direct/0] 00:25:28
                    >  via lo0.1
fc00:200:1:9::/64  *[Direct/0] 00:25:17
                    >  via et-0/0/12:0.0
fc00:200:1:10::/64 *[Direct/0] 00:25:17
                    >  via et-0/0/12:1.0
fc00:200:1:11::/64 *[Direct/0] 00:25:17
                    >  via et-0/0/13:0.0
fe80::5a86:70f0:7b:10d4/128
                   *[Direct/0] 00:25:28
                    >  via lo0.1
jnpr@stripe2-leaf2> show route protocol direct table Tenant-2.inet6.0
Tenant-2.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:2:2::/64  *[Direct/0] 00:24:51
                    >  via lo0.2
fc00:200:2:9::/64  *[Direct/0] 00:24:40
                    >  via et-0/0/12:0.0
fc00:200:2:10::/64 *[Direct/0] 00:24:40
                    >  via et-0/0/12:1.0
fc00:200:2:11::/64 *[Direct/0] 00:24:40
                    >  via et-0/0/13:0.0
fe80::5a86:70f0:79:99d4/128
                   *[Direct/0] 00:24:51
                    >  via lo0.2
To verify evpn l3 contexts including encapsulation, VNI, router MAC address use:
show evpn l3-contextshow evpn l3-context <tenant-name>
extensive
Example:
jnpr@stripe1-leaf1> show evpn l3-context
L3 context Type  Adv Encap  VNI/Label  Router MAC/GW intf dt4-sid dt6-sid dt46-sid
Tenant-1         Cfg Direct   VXLAN  20001      9c:5a:80:c1:b3:06
jnpr@stripe1-leaf2> show evpn l3-context
L3 context Type  Adv Encap  VNI/Label  Router MAC/GW intf dt4-sid dt6-sid dt46-sid
Tenant-2         Cfg Direct   VXLAN  20002      58:86:70:79:df:db
jnpr@stripe2-leaf1> show evpn l3-context
L3 context Type  Adv Encap  VNI/Label  Router MAC/GW intf dt4-sid dt6-sid dt46-sid
Tenant-1         Cfg Direct   VXLAN  20001      58:86:70:7b:10:db
jnpr@stripe2-leaf2> show evpn l3-context
L3 context Type  Adv Encap  VNI/Label  Router MAC/GW intf dt4-sid dt6-sid dt46-sid
Tenant-2         Cfg Direct   VXLAN  20002      58:86:70:79:99:db
jnpr@stripe1-leaf1> show evpn l3-context Tenant-1 extensive
L3 context: Tenant-1
  Type: Configured
  Advertisement mode: Direct nexthop, Router MAC: 9c:5a:80:c1:b3:06
  Encapsulation: VXLAN, VNI: 20001
  IPv6 source VTEP address: fc00:10:0:1::1
  IP->EVPN export policy: BGP-AOS-Policy-Tenant-1
  Flags: 0xc209 <Configured IRB-MAC ROUTING RT-INSTANCE-TARGET-IMPORT-POLICY RT-INSTANCE-TARGET-EXPORT-POLCIY>
  Change flags: 0x20000 <VXLAN-VNI-Update-RTT-OPQ>
  Composite nexthop support: Disabled
  Route Distinguisher: 10.0.1.1:2001
  Reference count: 9
  EVPN Multicast Routing mode: CRB
jnpr@stripe1-leaf2> show evpn l3-context Tenant-2 extensive
L3 context: Tenant-2
  Type: Configured
  Advertisement mode: Direct nexthop, Router MAC: 58:86:70:79:df:db
  Encapsulation: VXLAN, VNI: 20002
  IPv6 source VTEP address: fc00:10:0:1::2
  IP->EVPN export policy: BGP-AOS-Policy-Tenant-2
  Flags: 0xc209 <Configured IRB-MAC ROUTING RT-INSTANCE-TARGET-IMPORT-POLICY RT-INSTANCE-TARGET-EXPORT-POLCIY>
  Change flags: 0x20000 <VXLAN-VNI-Update-RTT-OPQ>
  Composite nexthop support: Disabled
  Route Distinguisher: 10.0.1.2:2002
  Reference count: 9
  EVPN Multicast Routing mode: CRB
jnpr@stripe1-leaf1> show evpn ip-prefix-database
L3 context: Tenant-1
IPv6->EVPN Exported Prefixes
Prefix                                       EVPN route status
fc00:100:1:1::/64                            Created
fc00:200:1:1::/64                            Created
fc00:200:1:2::/64                            Created
fc00:200:1:3::/64                            Created
EVPN->IPv6 Imported Prefixes
Prefix                                       Etag
fc00:100:2:1::/64                            0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.9:2001          20001                   58:86:70:7b:10:db  fc00:10:0:1::9            Accepted      n/a
fc00:200:1:9::/64                            0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.9:2001          20001                   58:86:70:7b:10:db  fc00:10:0:1::9            Accepted      n/a
fc00:200:1:10::/64                           0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.9:2001          20001                   58:86:70:7b:10:db  fc00:10:0:1::9            Accepted      n/a
fc00:200:1:11::/64                           0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.9:2001          20001                   58:86:70:7b:10:db  fc00:10:0:1::9            Accepted      n/a
jnpr@stripe1-leaf2> show evpn ip-prefix-database
L3 context: Tenant-2
IPv6->EVPN Exported Prefixes
Prefix                                       EVPN route status
fc00:100:1:2::/64                            Created
fc00:200:2:1::/64                            Created
fc00:200:2:2::/64                            Created
fc00:200:2:3::/64                            Created
EVPN->IPv6 Imported Prefixes
Prefix                                       Etag
fc00:100:2:2::/64                            0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.10:2002         20002                   58:86:70:79:99:db  fc00:10:0:1::10           Accepted      n/a
fc00:200:2:9::/64                            0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.10:2002         20002                   58:86:70:79:99:db  fc00:10:0:1::10           Accepted      n/a
fc00:200:2:10::/64                           0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.10:2002         20002                   58:86:70:79:99:db  fc00:10:0:1::10           Accepted      n/a
fc00:200:2:11::/64                           0
  Route distinguisher    VNI/Label/SID           Router MAC         Nexthop/Overlay GW/ESI   Route-Status  Reject-Reason
  10.0.1.10:2002         20002                   58:86:70:79:99:db  fc00:10:0:1::10           Accepted      n/a
You can verify that the expected routes for each tenant are being advertised by the leaf
nodes using: show route advertising-protocol bgp <peer-id> table
<tenant-name>.evpn.0
Example:
jnpr@stripe1-leaf1> show route advertising-protocol bgp FC00:10::1 table Tenant-1.evpn.0
Tenant-1.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
*                         Self                                    I
  5:10.0.1.1:2001::0::fc00:200:1:1::::64/248
*                         Self                                    I
  5:10.0.1.1:2001::0::fc00:200:1:2::::64/248
*                         Self                                    I
  5:10.0.1.1:2001::0::fc00:200:1:3::::64/248
*                         Self                                    I
jnpr@stripe1-leaf2> show route advertising-protocol bgp FC00:10::1 table Tenant-2.evpn.0
Tenant-2.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
*                         Self                                    I
  5:10.0.1.2:2002::0::fc00:200:2:1::::64/248
*                         Self                                    I
  5:10.0.1.2:2002::0::fc00:200:2:2::::64/248
*                         Self                                    I
  5:10.0.1.2:2002::0::fc00:200:2:3::::64/248
*                         Self                                    I
jnpr@stripe2-leaf1> show route advertising-protocol bgp FC00:10::1 table Tenant-1.evpn.0
Tenant-1.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.9:2001::0::fc00:100:2:1::::64/248
*                         Self                                    I
  5:10.0.1.9:2001::0::fc00:200:1:9::::64/248
*                         Self                                    I
  5:10.0.1.9:2001::0::fc00:200:1:10::::64/248
*                         Self                                    I
  5:10.0.1.9:2001::0::fc00:200:1:11::::64/248
*                         Self                                    I
jnpr@stripe2-leaf2> show route advertising-protocol bgp FC00:10::1 table Tenant-2.evpn.0
Tenant-2.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.10:2002::0::fc00:100:2:2::::64/248
*                         Self                                    I
  5:10.0.1.10:2002::0::fc00:200:2:9::::64/248
*                         Self                                    I
  5:10.0.1.10:2002::0::fc00:200:2:10::::64/248
*                         Self                                    I
  5:10.0.1.10:2002::0::fc00:200:2:11::::64/248
*                         Self                                    I
You can verify that the expected routes for each tenant, are being received by the leaf
nodes, and installed in the correct routing table use: show route receive-protocol
bgp <peer-id> table <tenant-name>.evpn.0show route table
Tenant-1.inet6.0 protocol evpn
Example:
jnpr@stripe1-leaf1> show route receive-protocol bgp FC00:10::1 table Tenant-1.evpn.0
Tenant-1.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.9:2001::0::fc00:100:2:1::::64/248
                          fc00:10:0:1::9                          101 209 I
  5:10.0.1.9:2001::0::fc00:200:1:9::::64/248
                          fc00:10:0:1::9                          101 209 I
  5:10.0.1.9:2001::0::fc00:200:1:10::::64/248
                          fc00:10:0:1::9                          101 209 I
  5:10.0.1.9:2001::0::fc00:200:1:11::::64/248
                          fc00:10:0:1::9                          101 209 I
jnpr@stripe1-leaf1> show route table Tenant-1.inet6.0 protocol evpn
Tenant-1.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:2:1::/64  *[EVPN/170] 00:20:14
                       to fe80::9e5a:80ff:feef:a28f via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0d5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:ced5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3d5 via et-0/0/33:0.0
fc00:200:1:9::/64  *[EVPN/170] 00:20:14
                       to fe80::9e5a:80ff:feef:a28f via et-0/0/30:0.0
                    >  to fe80::5a86:70ff:fe78:e0d5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:ced5 via et-0/0/32:0.0
                       to fe80::5a86:70ff:fe79:3d5 via et-0/0/33:0.0
fc00:200:1:10::/64 *[EVPN/170] 00:20:14
                       to fe80::9e5a:80ff:feef:a28f via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0d5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:ced5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3d5 via et-0/0/33:0.0
fc00:200:1:11::/64 *[EVPN/170] 00:20:14
                       to fe80::9e5a:80ff:feef:a28f via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0d5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:ced5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3d5 via et-0/0/33:0.0
jnpr@stripe1-leaf2> show route receive-protocol bgp FC00:10::1 table Tenant-2.evpn.0
Tenant-2.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.10:2002::0::fc00:100:2:2::::64/248
                          fc00:10:0:1::10                         101 210 I
  5:10.0.1.10:2002::0::fc00:200:2:9::::64/248
                          fc00:10:0:1::10                         101 210 I
  5:10.0.1.10:2002::0::fc00:200:2:10::::64/248
                          fc00:10:0:1::10                         101 210 I
  5:10.0.1.10:2002::0::fc00:200:2:11::::64/248
                          fc00:10:0:1::10                         101 210 I
jnpr@stripe1-leaf2> show route table Tenant-2.inet6.0 protocol evpn
Tenant-2.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:2:2::/64  *[EVPN/170] 00:22:12
                       to fe80::9e5a:80ff:feef:a297 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0dd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cedd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3dd via et-0/0/33:0.0
fc00:200:2:9::/64  *[EVPN/170] 00:22:12
                       to fe80::9e5a:80ff:feef:a297 via et-0/0/30:0.0
                    >  to fe80::5a86:70ff:fe78:e0dd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cedd via et-0/0/32:0.0
                       to fe80::5a86:70ff:fe79:3dd via et-0/0/33:0.0
fc00:200:2:10::/64 *[EVPN/170] 00:22:12
                       to fe80::9e5a:80ff:feef:a297 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0dd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cedd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3dd via et-0/0/33:0.0
fc00:200:2:11::/64 *[EVPN/170] 00:22:12
                       to fe80::9e5a:80ff:feef:a297 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0dd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cedd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3dd via et-0/0/33:0.0
jnpr@stripe2-leaf1> show route receive-protocol bgp FC00:10::1 table Tenant-1.evpn.0
Tenant-1.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.1:2001::0::fc00:100:1:1::::64/248
                          fc00:10:0:1::1                          101 201 I
  5:10.0.1.1:2001::0::fc00:200:1:1::::64/248
                          fc00:10:0:1::1                          101 201 I
  5:10.0.1.1:2001::0::fc00:200:1:2::::64/248
                          fc00:10:0:1::1                          101 201 I
  5:10.0.1.1:2001::0::fc00:200:1:3::::64/248
                          fc00:10:0:1::1                          101 201 I
jnpr@stripe2-leaf1> show route table Tenant-1.inet6.0 protocol evpn
Tenant-1.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:1:1::/64  *[EVPN/170] 00:22:04
                       to fe80::9e5a:80ff:feef:a2af via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0f5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cef5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3f5 via et-0/0/33:0.0
fc00:200:1:1::/64  *[EVPN/170] 00:22:04
                       to fe80::9e5a:80ff:feef:a2af via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0f5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cef5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3f5 via et-0/0/33:0.0
fc00:200:1:2::/64  *[EVPN/170] 00:22:04
                       to fe80::9e5a:80ff:feef:a2af via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0f5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cef5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3f5 via et-0/0/33:0.0
fc00:200:1:3::/64  *[EVPN/170] 00:22:04
                       to fe80::9e5a:80ff:feef:a2af via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0f5 via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cef5 via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3f5 via et-0/0/33:0.0
jnpr@stripe2-leaf2> show route receive-protocol bgp FC00:10::1 table Tenant-2.evpn.0
Tenant-2.evpn.0: 8 destinations, 20 routes (8 active, 0 holddown, 0 hidden)
Restart Complete
  Prefix                  Nexthop              MED     Lclpref    AS path
  5:10.0.1.2:2002::0::fc00:100:1:2::::64/248
                          fc00:10:0:1::2                          101 202 I
  5:10.0.1.2:2002::0::fc00:200:2:1::::64/248
                          fc00:10:0:1::2                          101 202 I
  5:10.0.1.2:2002::0::fc00:200:2:2::::64/248
                          fc00:10:0:1::2                          101 202 I
  5:10.0.1.2:2002::0::fc00:200:2:3::::64/248
                          fc00:10:0:1::2                          101 202 I
jnpr@stripe2-leaf2> show route table Tenant-2.inet6.0 protocol evpn
Tenant-2.inet6.0: 17 destinations, 17 routes (17 active, 0 holddown, 0 hidden)
Restart Complete
@ = Routing Use Only, # = Forwarding Use Only
+ = Active Route, - = Last Active, * = Both
fc00:100:1:2::/64  *[EVPN/170] 00:22:16
                       to fe80::9e5a:80ff:feef:a2b7 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0fd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cefd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3fd via et-0/0/33:0.0
fc00:200:2:1::/64  *[EVPN/170] 00:22:16
                       to fe80::9e5a:80ff:feef:a2b7 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0fd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cefd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3fd via et-0/0/33:0.0
fc00:200:2:2::/64  *[EVPN/170] 00:22:16
                       to fe80::9e5a:80ff:feef:a2b7 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0fd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cefd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3fd via et-0/0/33:0.0
fc00:200:2:3::/64  *[EVPN/170] 00:22:16
                       to fe80::9e5a:80ff:feef:a2b7 via et-0/0/30:0.0
                       to fe80::5a86:70ff:fe78:e0fd via et-0/0/31:0.0
                       to fe80::5a86:70ff:fe7b:cefd via et-0/0/32:0.0
                    >  to fe80::5a86:70ff:fe79:3fd via et-0/0/33:0.0